Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
LLM Explainability or Controllability Improvements with Tensor Networks ...
How to Re-Code LLMs Layer by Layer with Tensor Network Substitutions ...
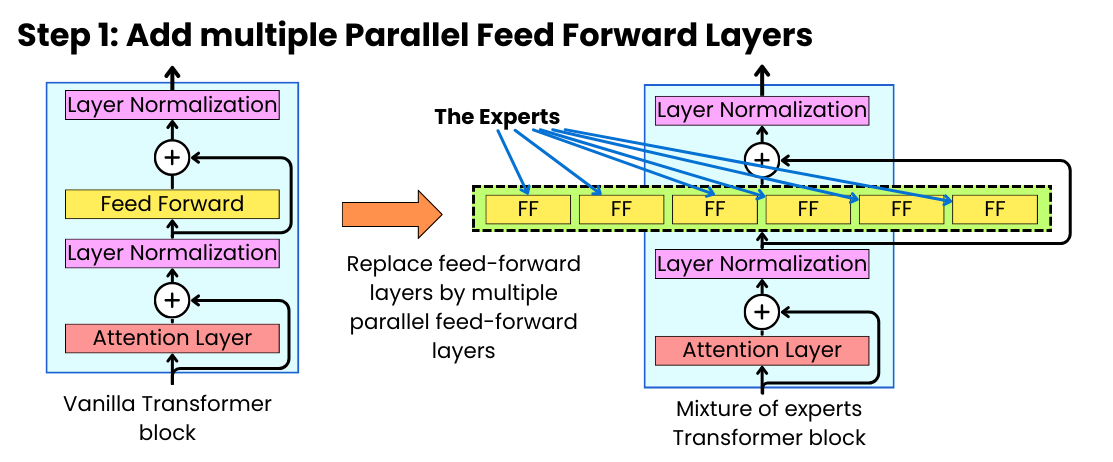
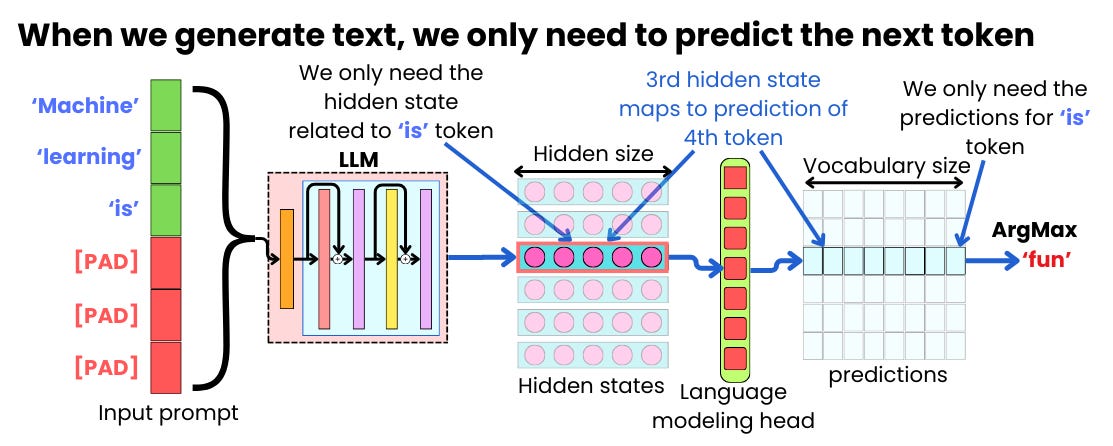
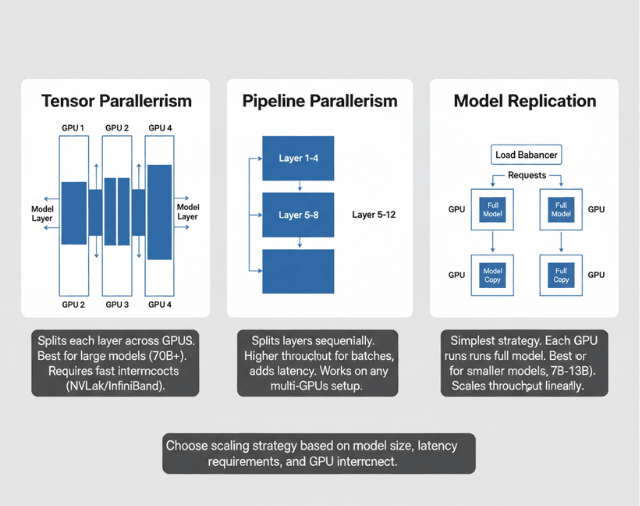
How to Scale LLM Inference - by Damien Benveniste
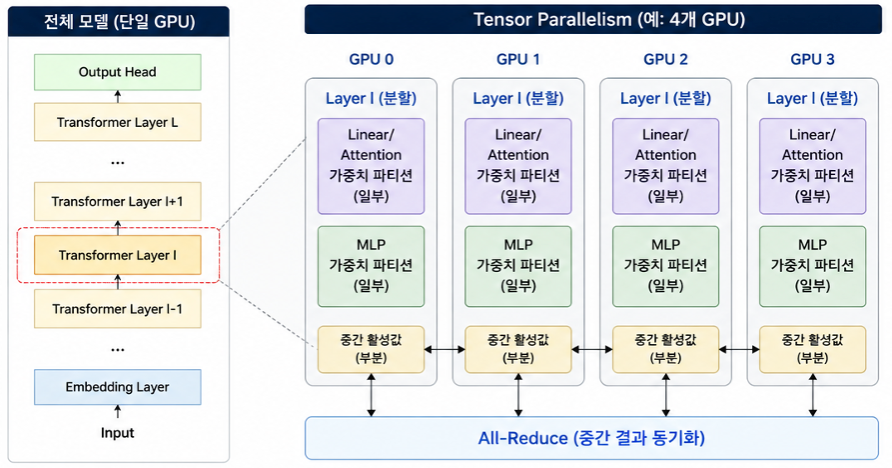
Large Scale Transformer model training with Tensor Parallel (TP) — 파이토치 ...
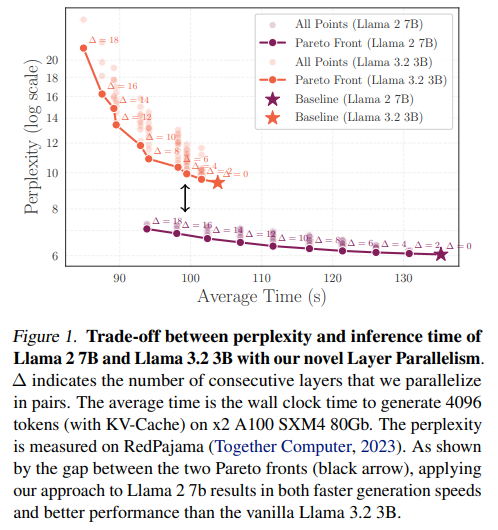
Layer Parallelism: Enhancing LLM Inference Efficiency Through Parallel ...
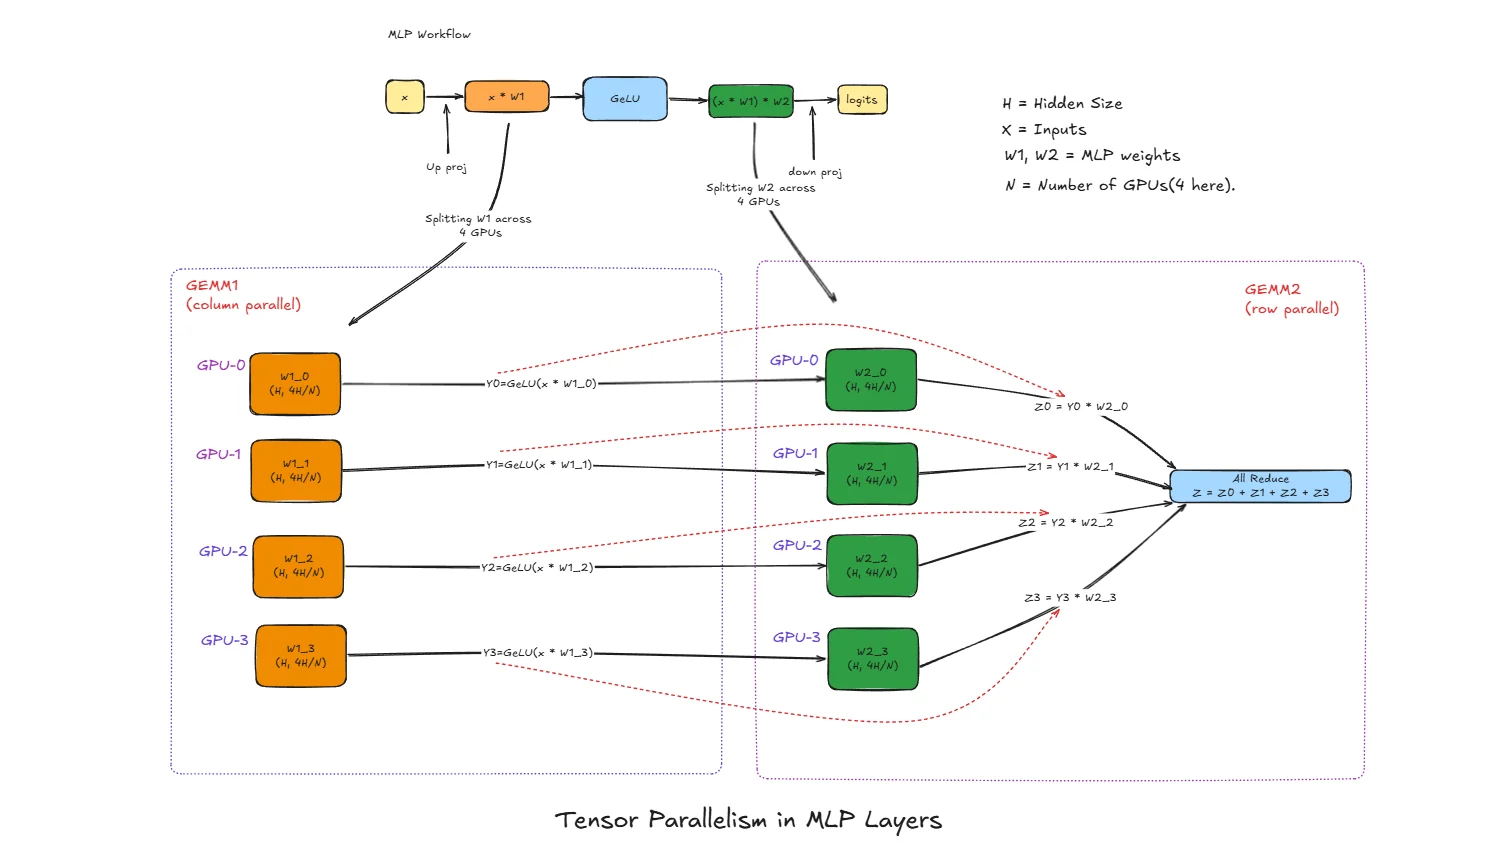
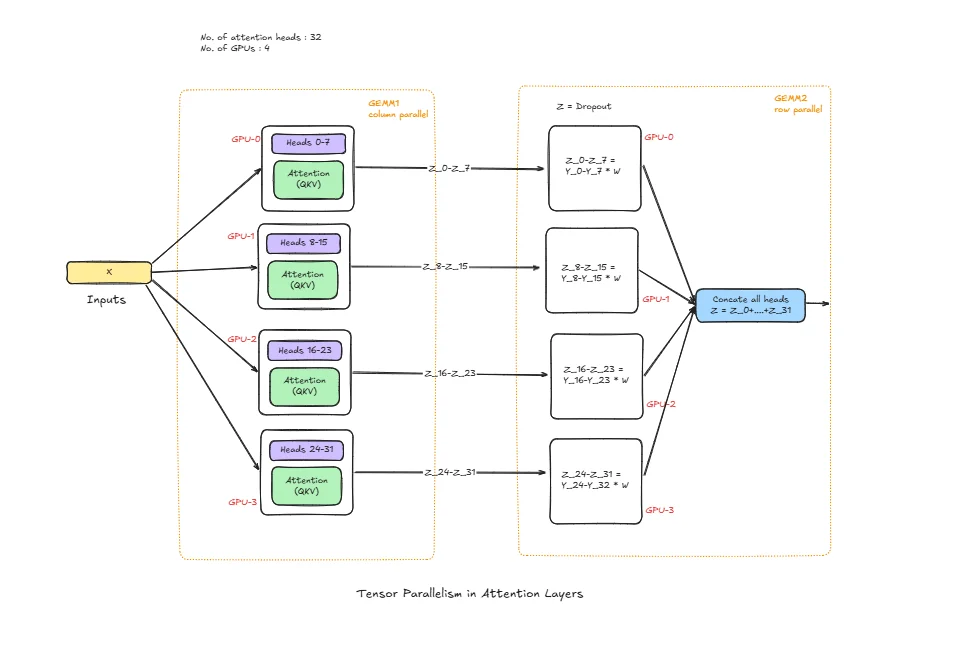
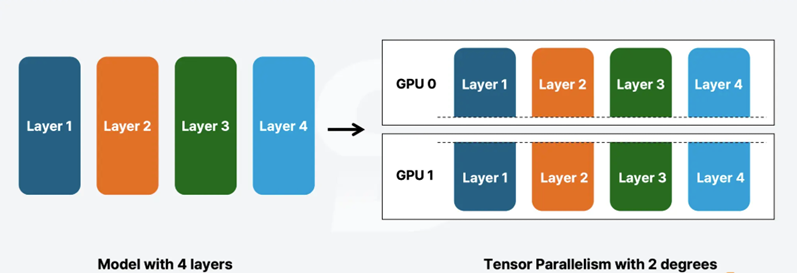
Tensor Parallel LLM Inferencing. As models increase in size, it becomes ...
Amoeba: Runtime Tensor Parallel Transformation for LLM Inference Services
Optimizing LLM Inference. A Large Language Model (LLM) such as… | by Dr ...
Amazon EC2 G5/G6 인스턴스에서 GPU Tensor Parallelism으로 비용 효과적으로 LLM 서빙하기 ...
Scaling Up LLM Pretraining: Parallel Training | PDF
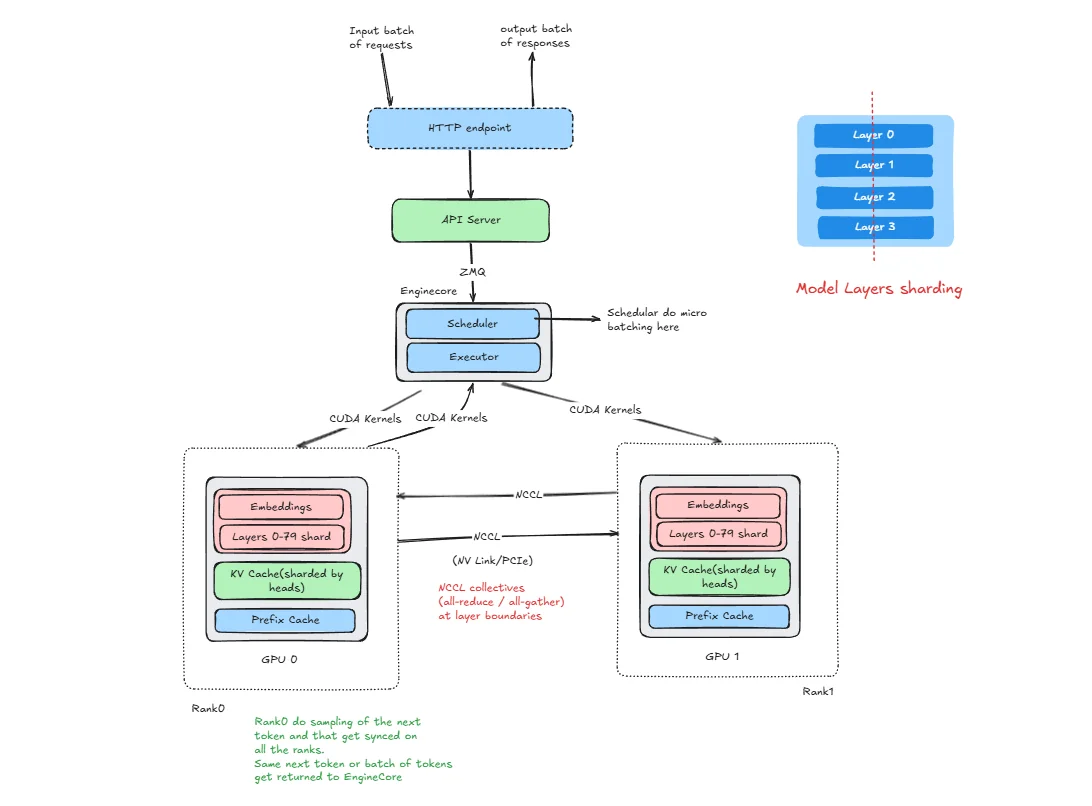
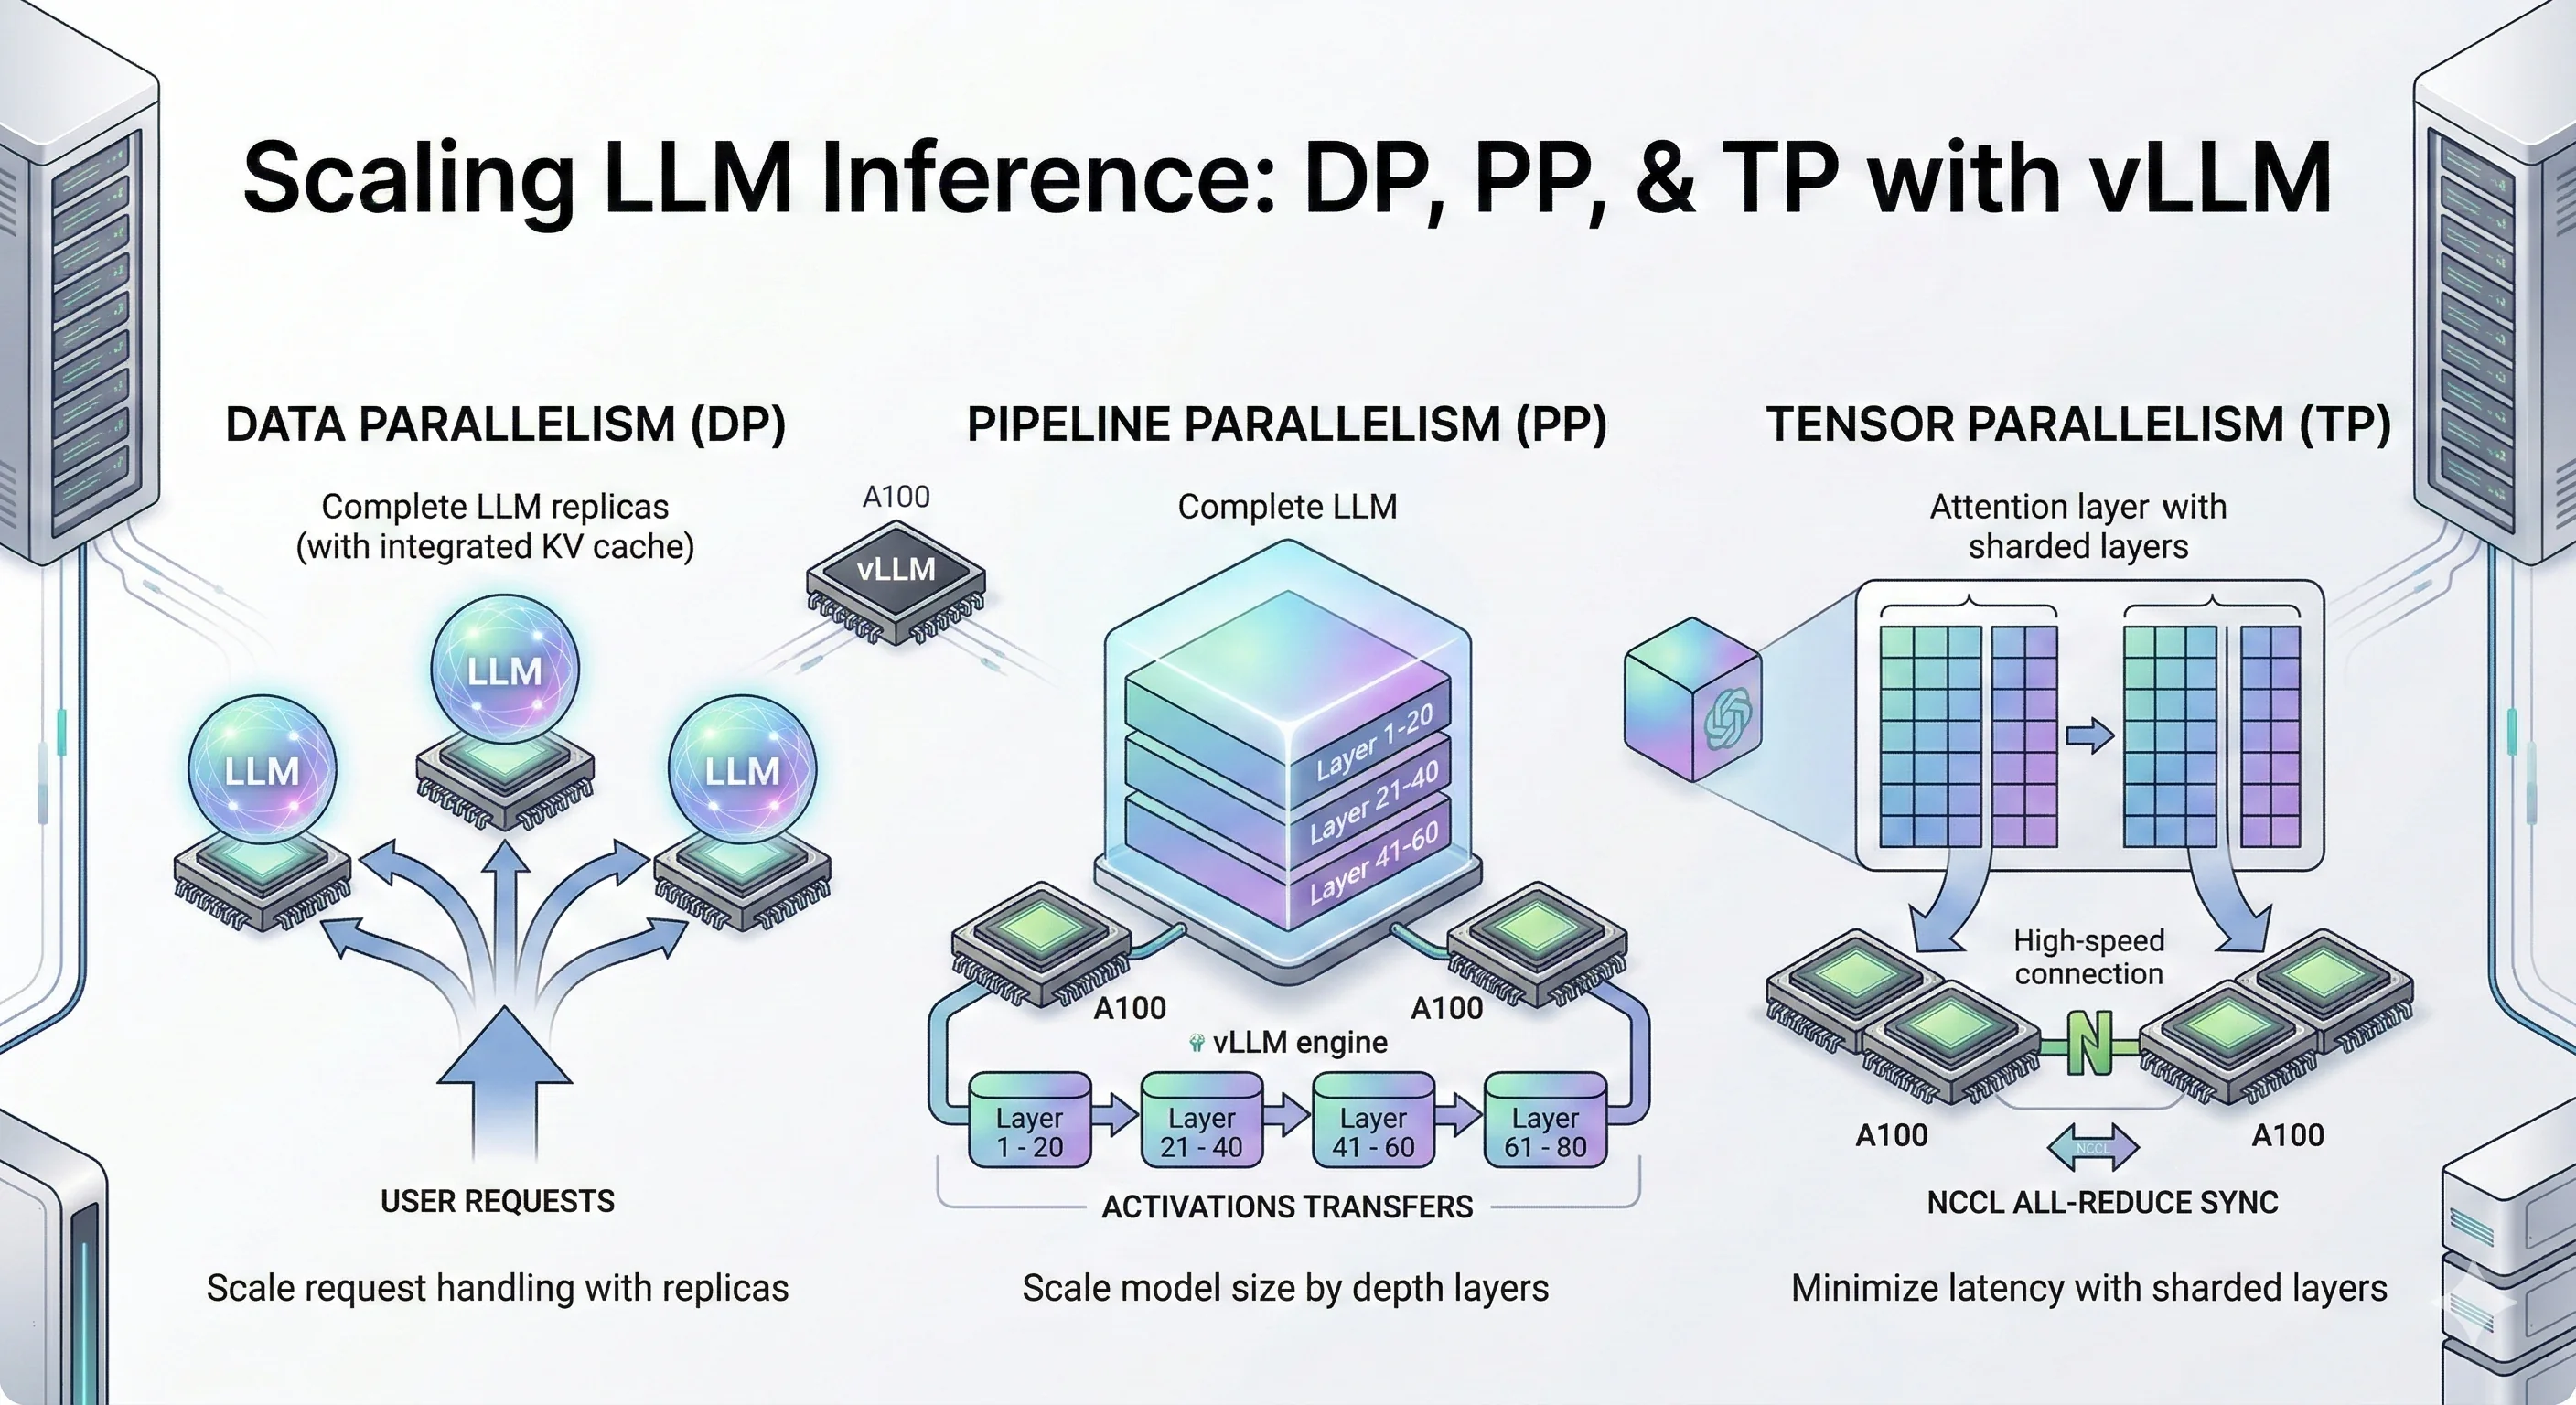
Scaling LLM Inference: Data, Pipeline & Tensor Parallelism in vLLM ...
[Literature Review] LESA: Learnable LLM Layer Scaling-Up
Optimizing Intra-Layer Parallel Communication for LLM Training on ...
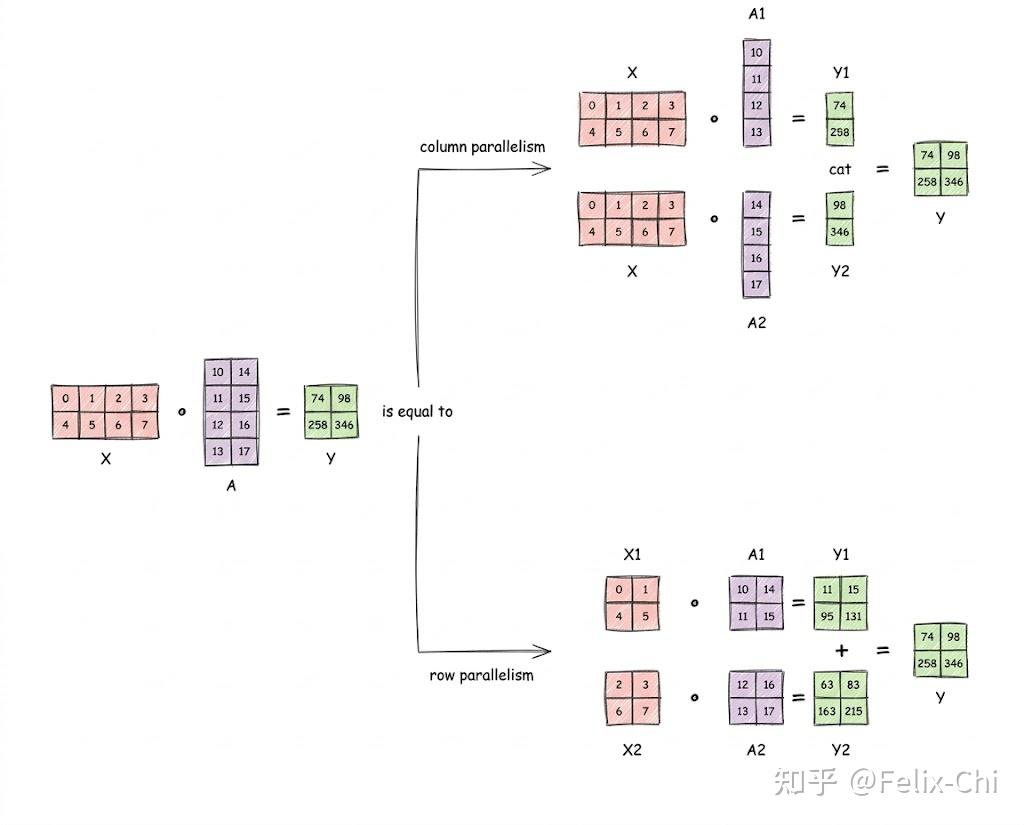
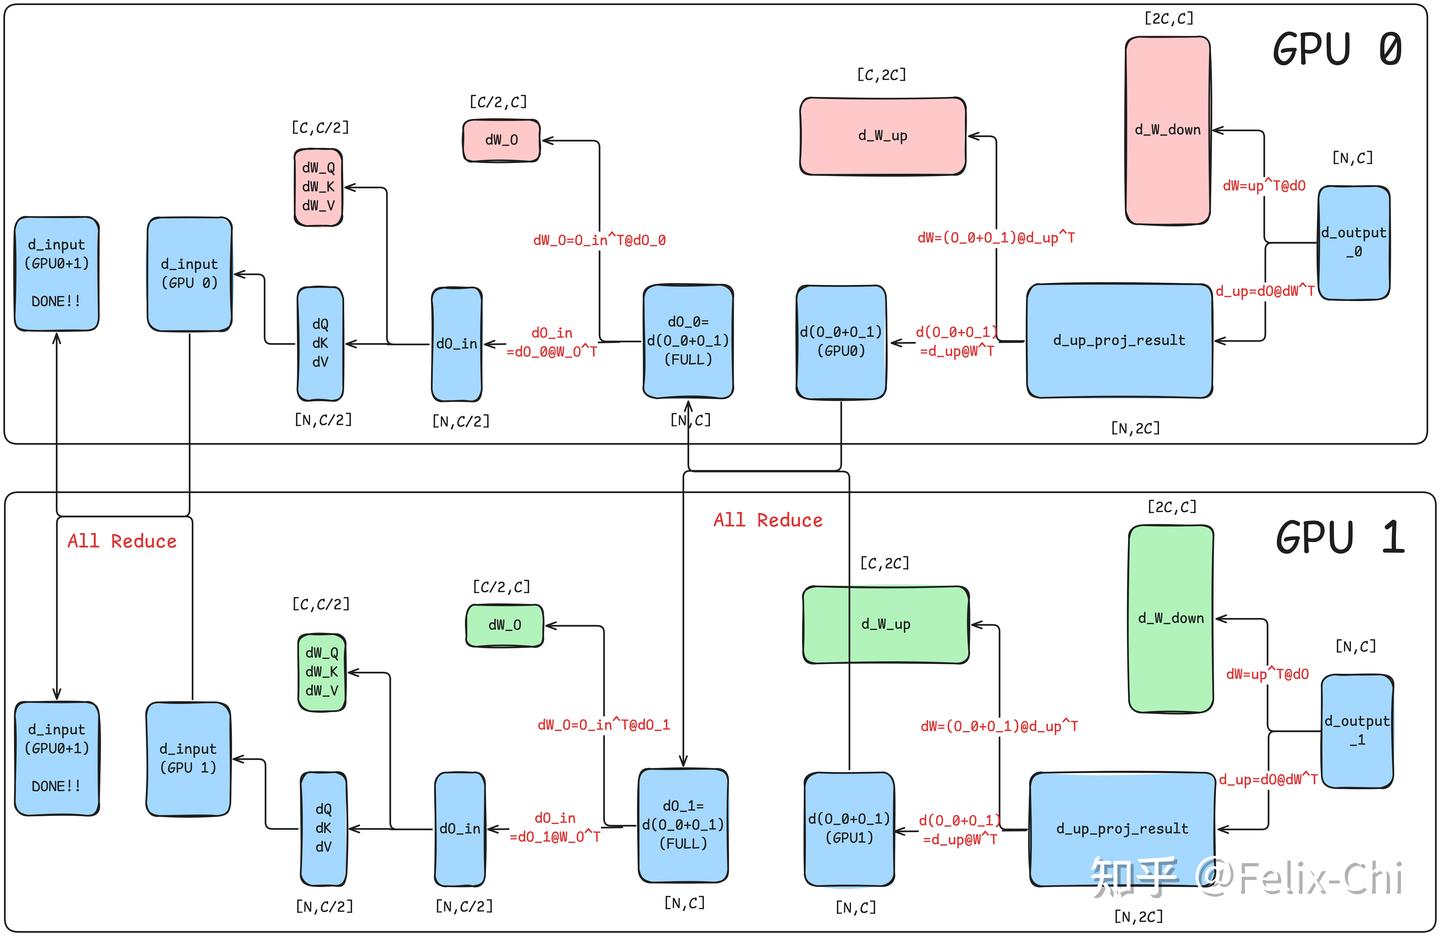
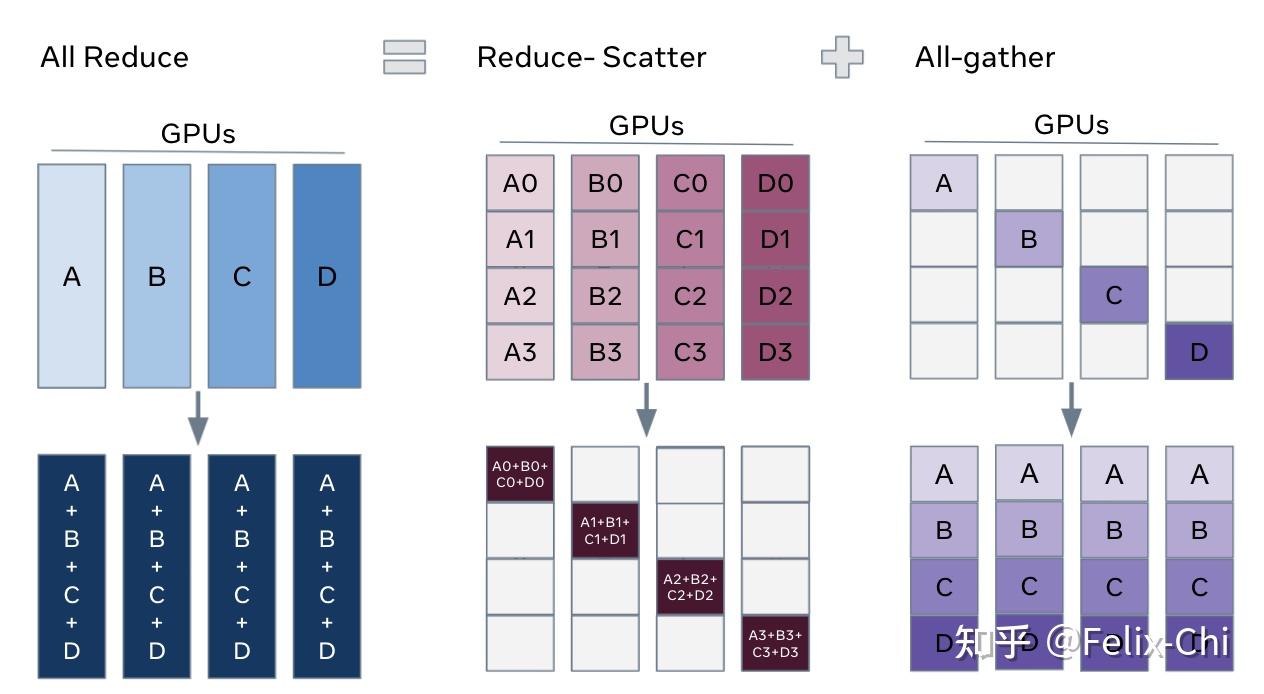
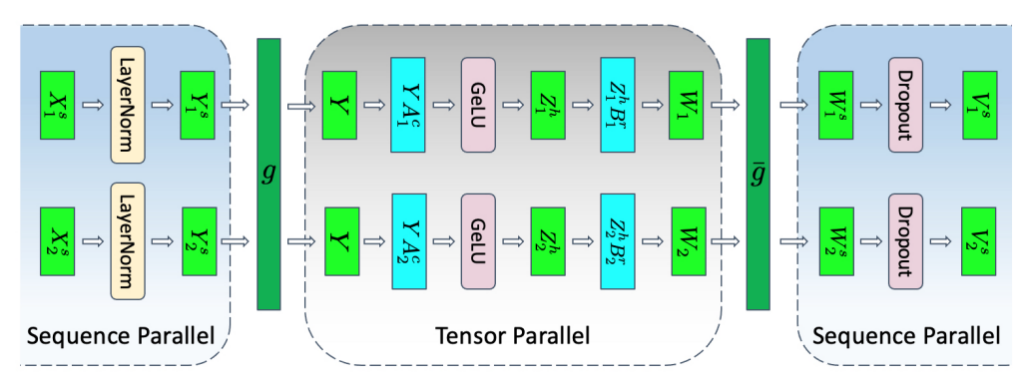
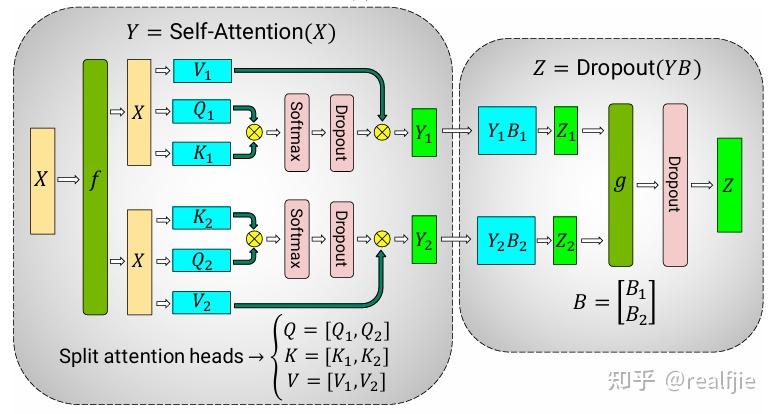
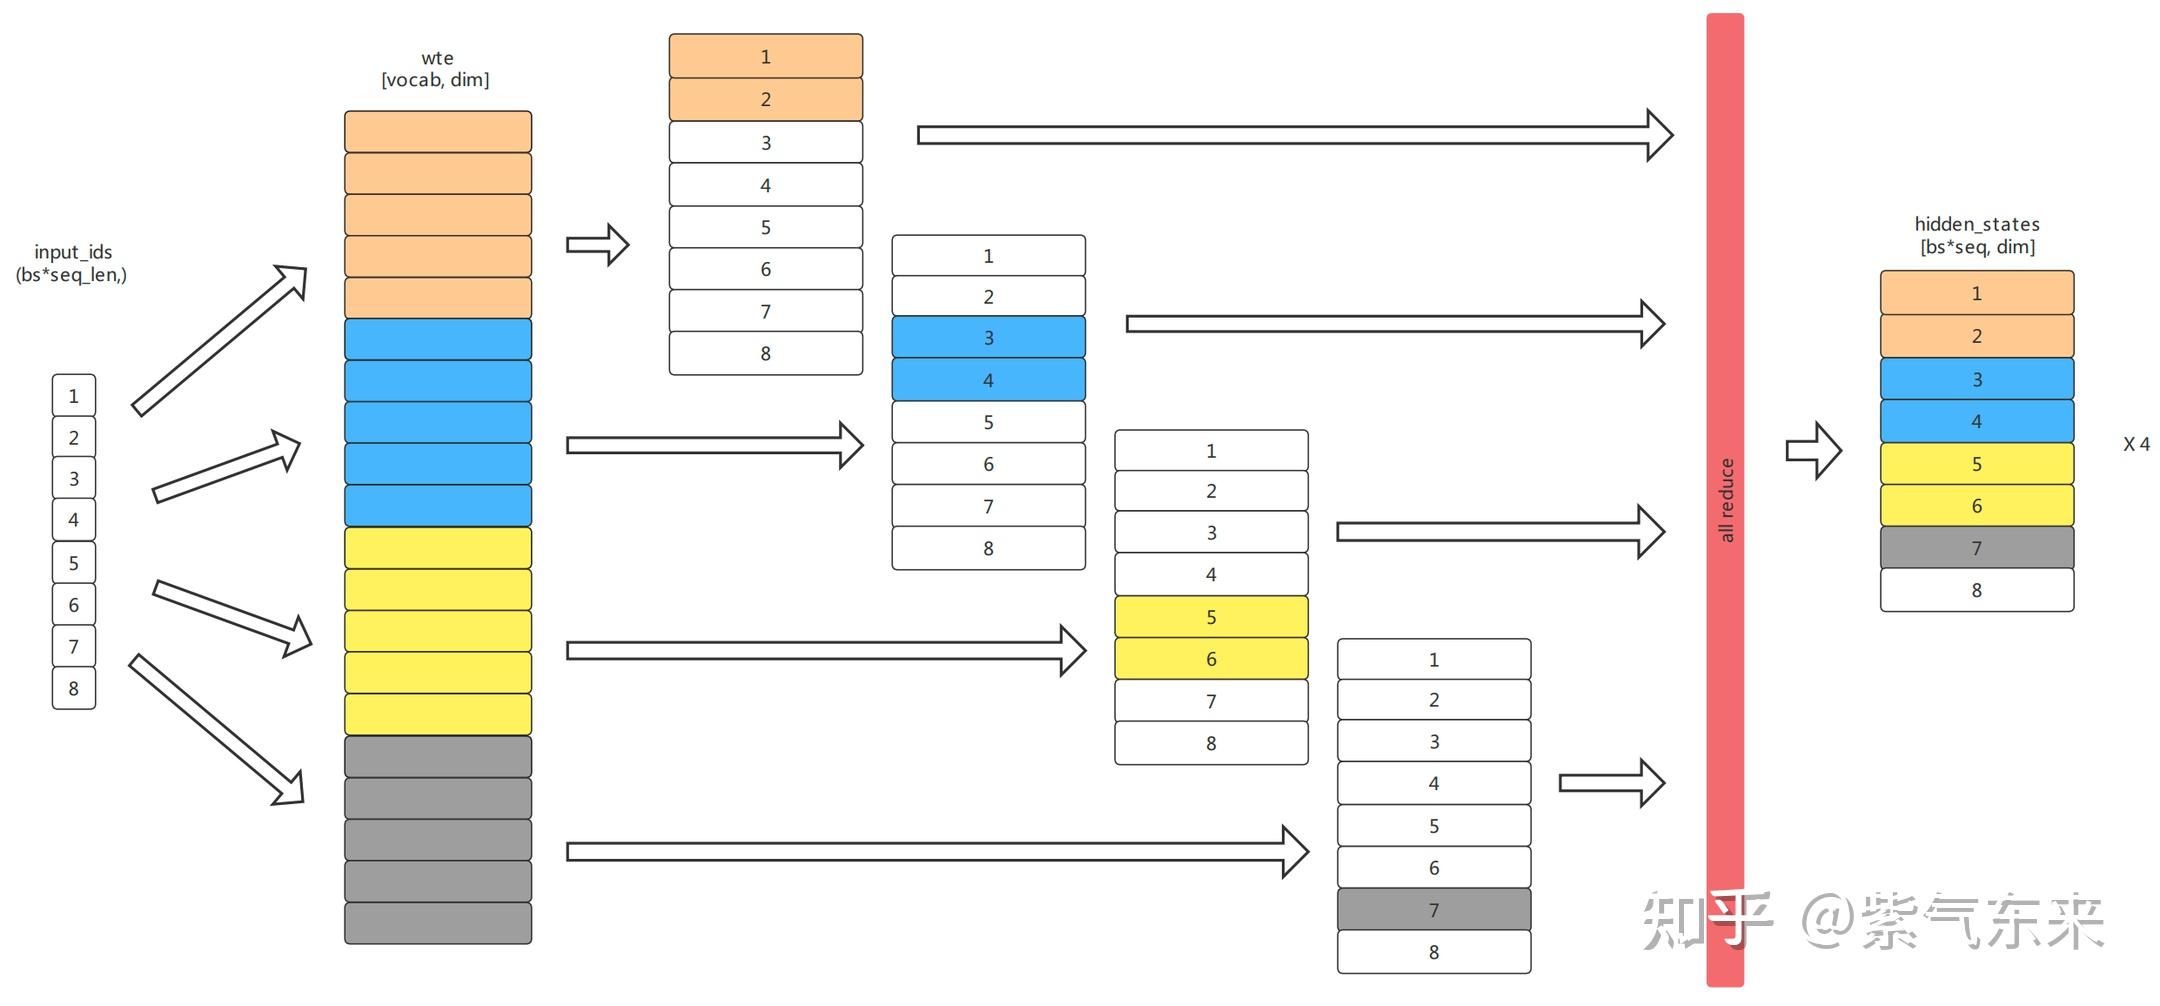
吃透LLM并行范式系列2 - Tensor Parallel和Sequence Parallel - 知乎
[논문 리뷰] Lossless Compression for LLM Tensor Incremental Snapshots
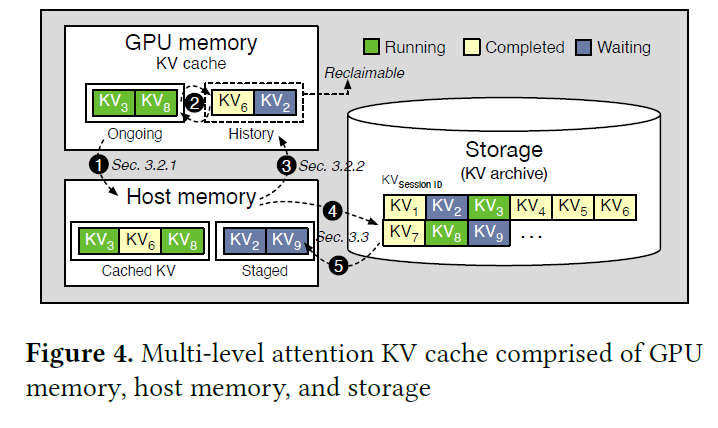
[PDF] LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM ...
FocusLLM: Scaling LLM's Context by Parallel Decoding
May Papers: Parallel scaling, Evolving code, Understanding LLM reasoning
The Application Layer for LLM Applications
AnchorTP: Resilient LLM Inference with State-Preserving Elastic Tensor ...
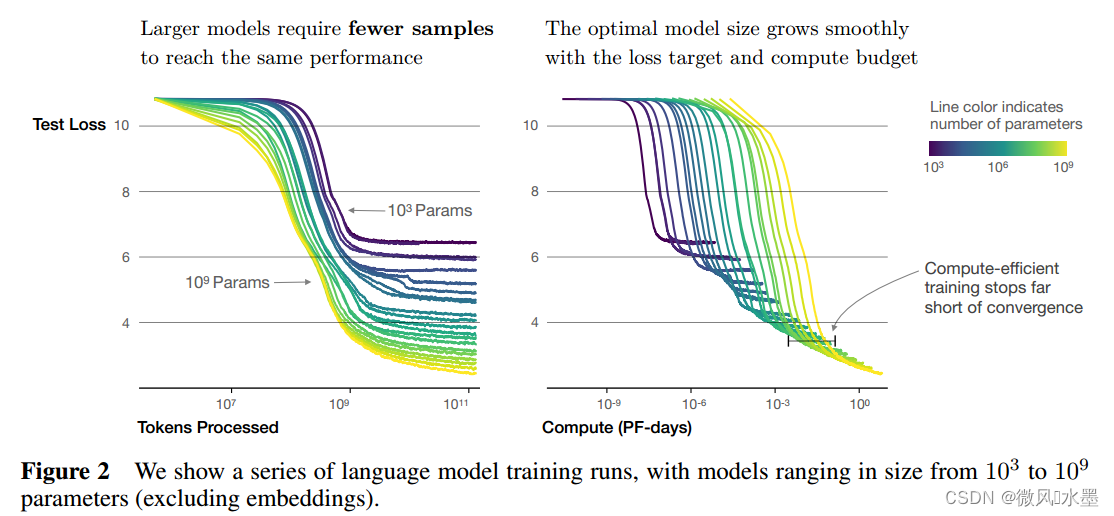
The Evolution of LLM Scaling Laws: From OpenAI to Chinchilla | by LM Po ...
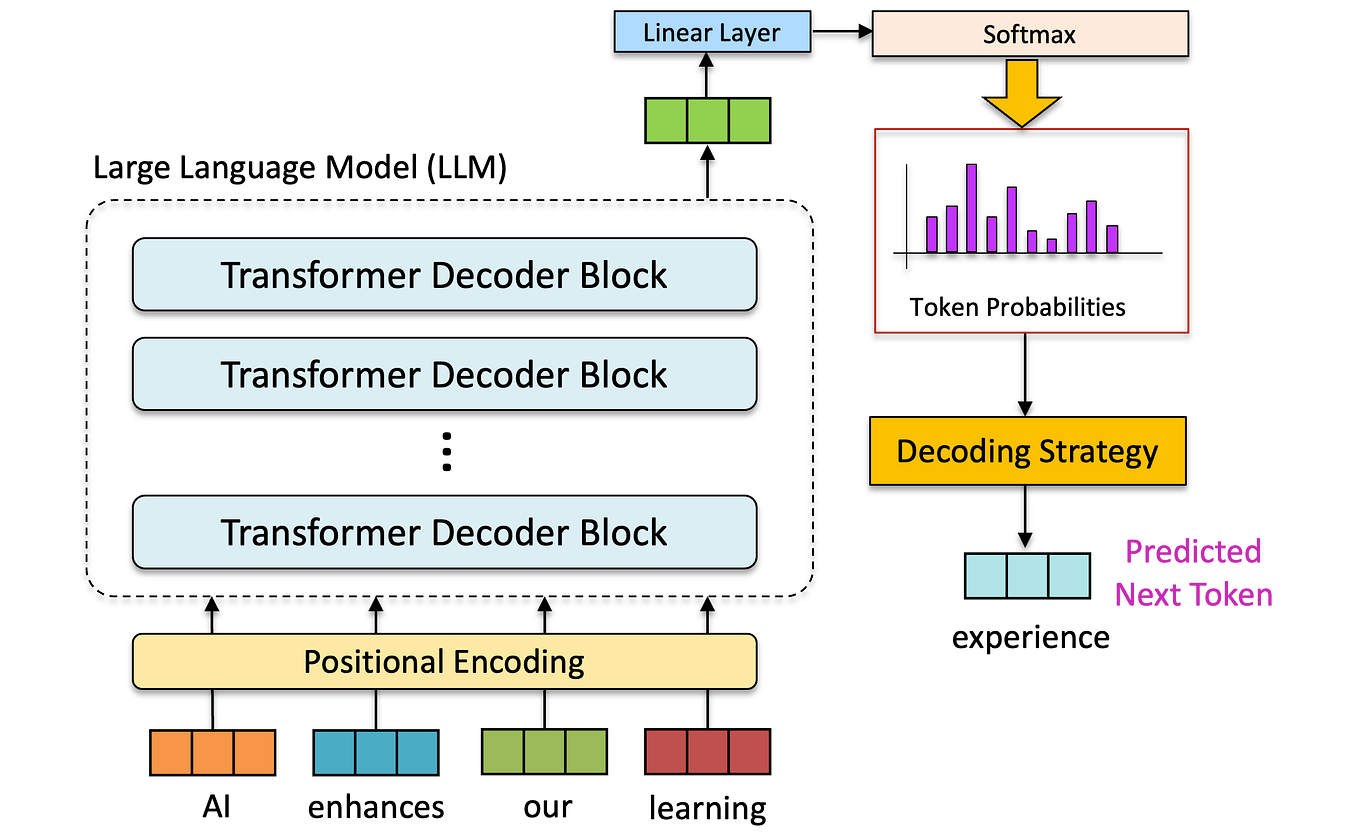
Understanding LLM Inference - by Alex Razvant
[논문 리뷰] LUT Tensor Core: Lookup Table Enables Efficient Low-Bit LLM ...
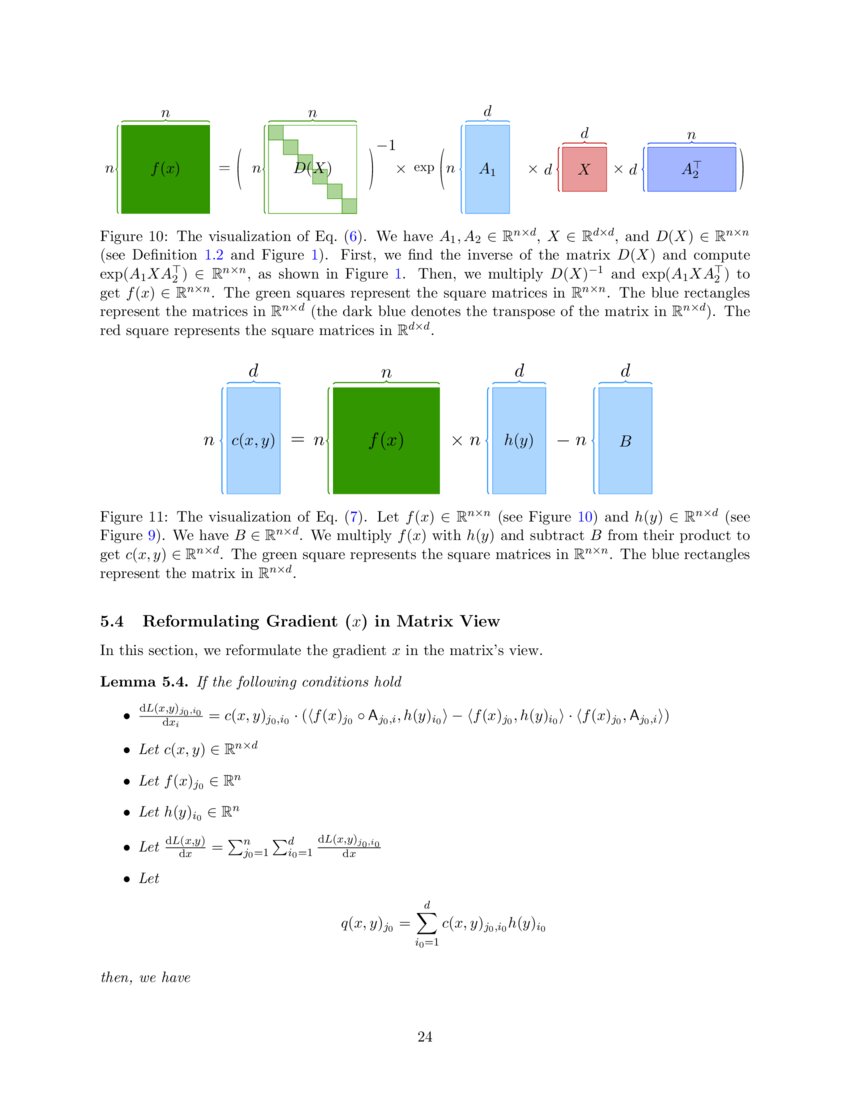
A Fast Optimization View: Reformulating Single Layer Attention in LLM ...
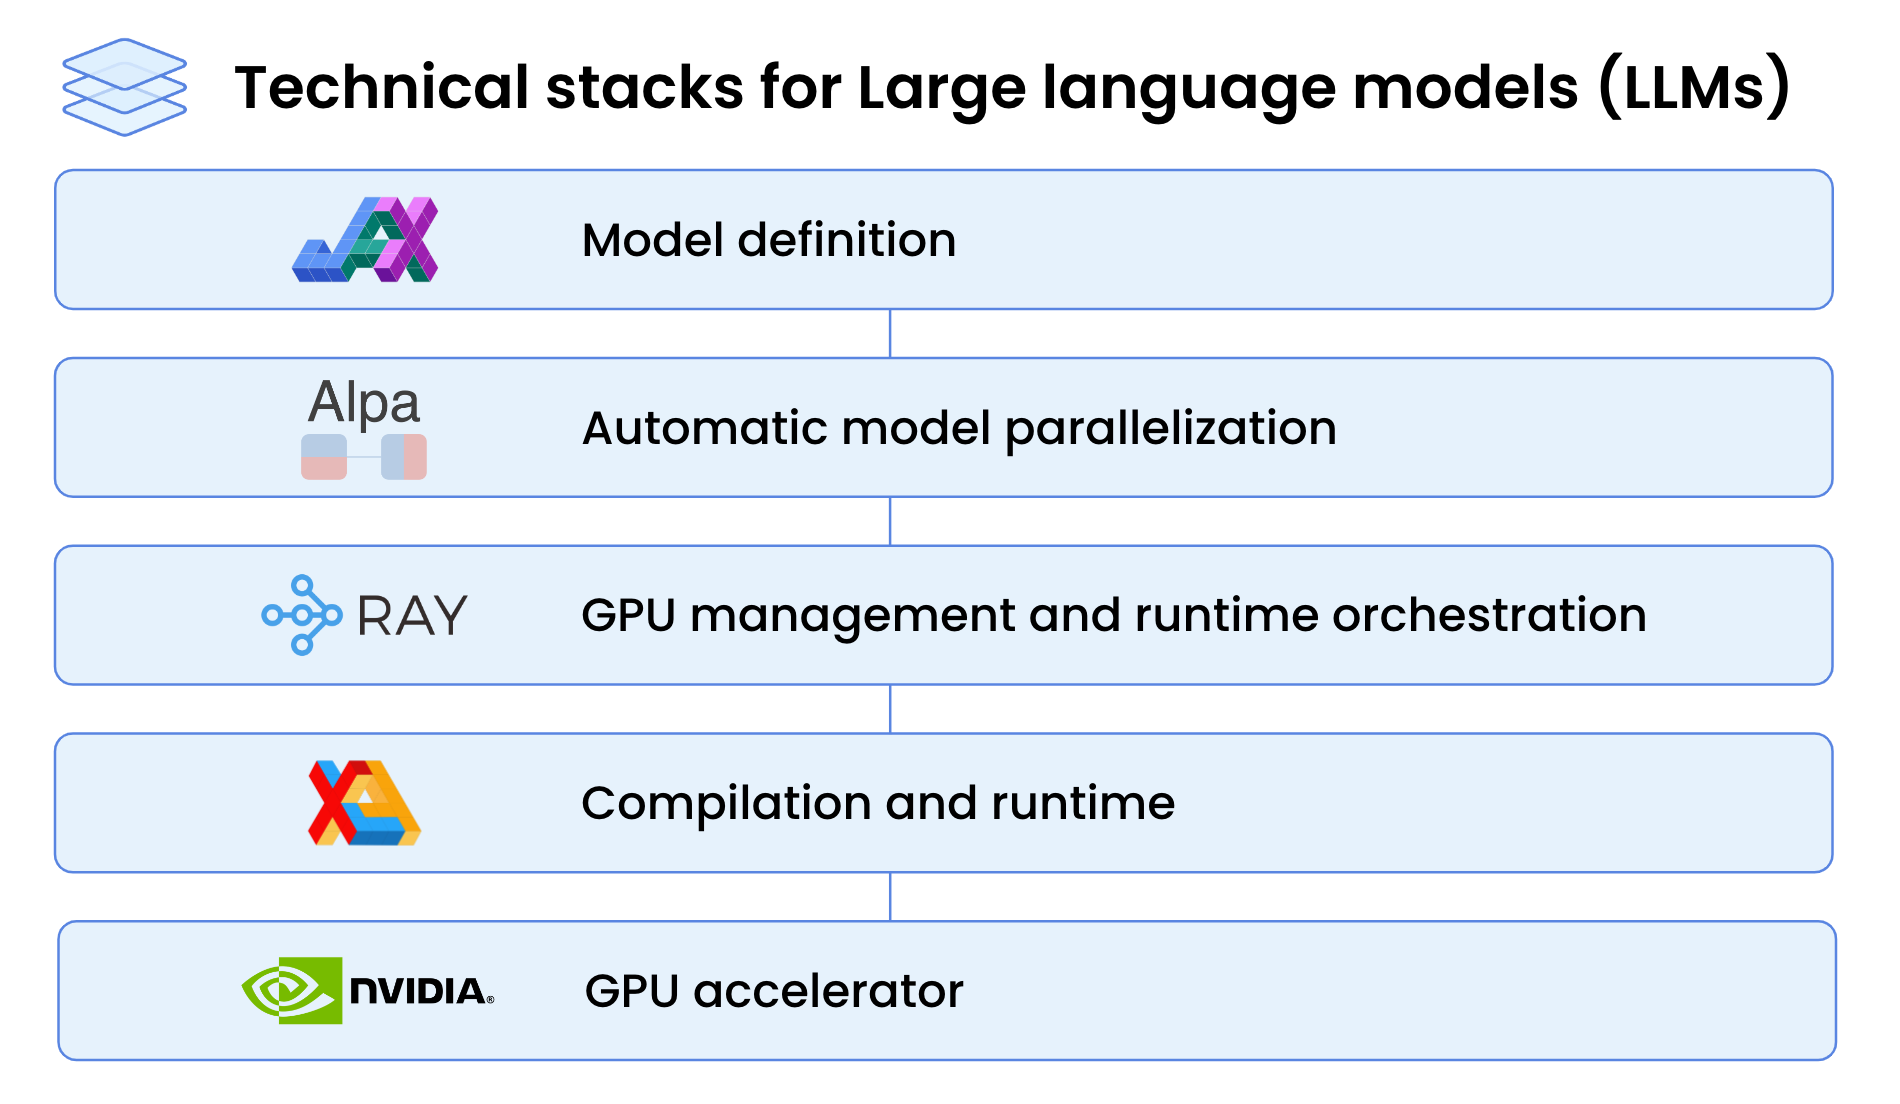
High-Performance LLM Training at 1000 GPU Scale With Alpa & Ray
LLM in the Parallel Learning Framework. | Download Scientific Diagram
FocusLLM: Scaling LLM's Context by Parallel Decoding | AI Research ...
1-Bit LLM and the 1.58 Bit LLM- The Magic of Model Quantization | by Dr ...
Mastering LLM Techniques: Inference Optimization | NVIDIA Technical Blog
RAG in the era of long-context LLMs | by Charles Godfrey | Thomson ...
GPU Guide for LLM Deployment - RTX 4090 to A100 Benchmarks (2026)
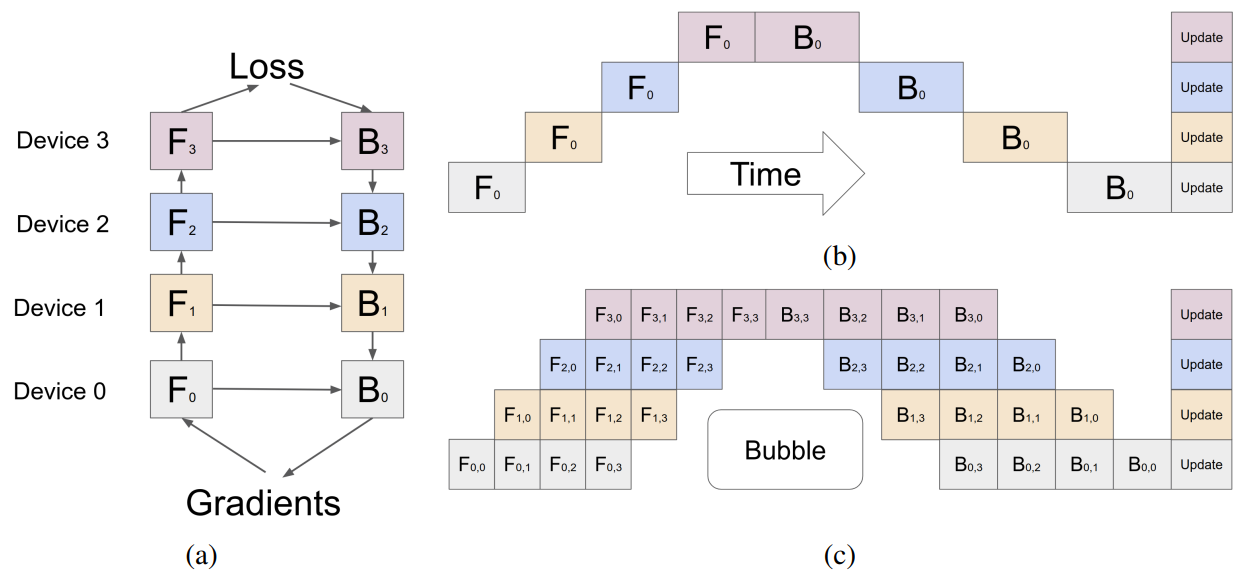
gLLM: Global Balanced Pipeline Parallelism System for Distributed LLM ...
Run your own AI at scale: Tuning vLLM for Superb LLM Deployment (Vol. 1 ...
The NeurIPS 2023 LLM Efficiency Challenge Starter Guide - Lightning AI
Scaling to Millions of Tokens with Efficient Long-Context LLM Training ...
[AI] 폐쇄형 LLM 시스템 구축
Figure 1 from APT-LLM: Exploiting Arbitrary-Precision Tensor Core ...
Optimizing Inference Efficiency for LLMs at Scale with NVIDIA NIM ...
What is a Tensor? Shape, Dims/Rank, and DType Explained | by Afzal ...
Understanding LLM Parameters
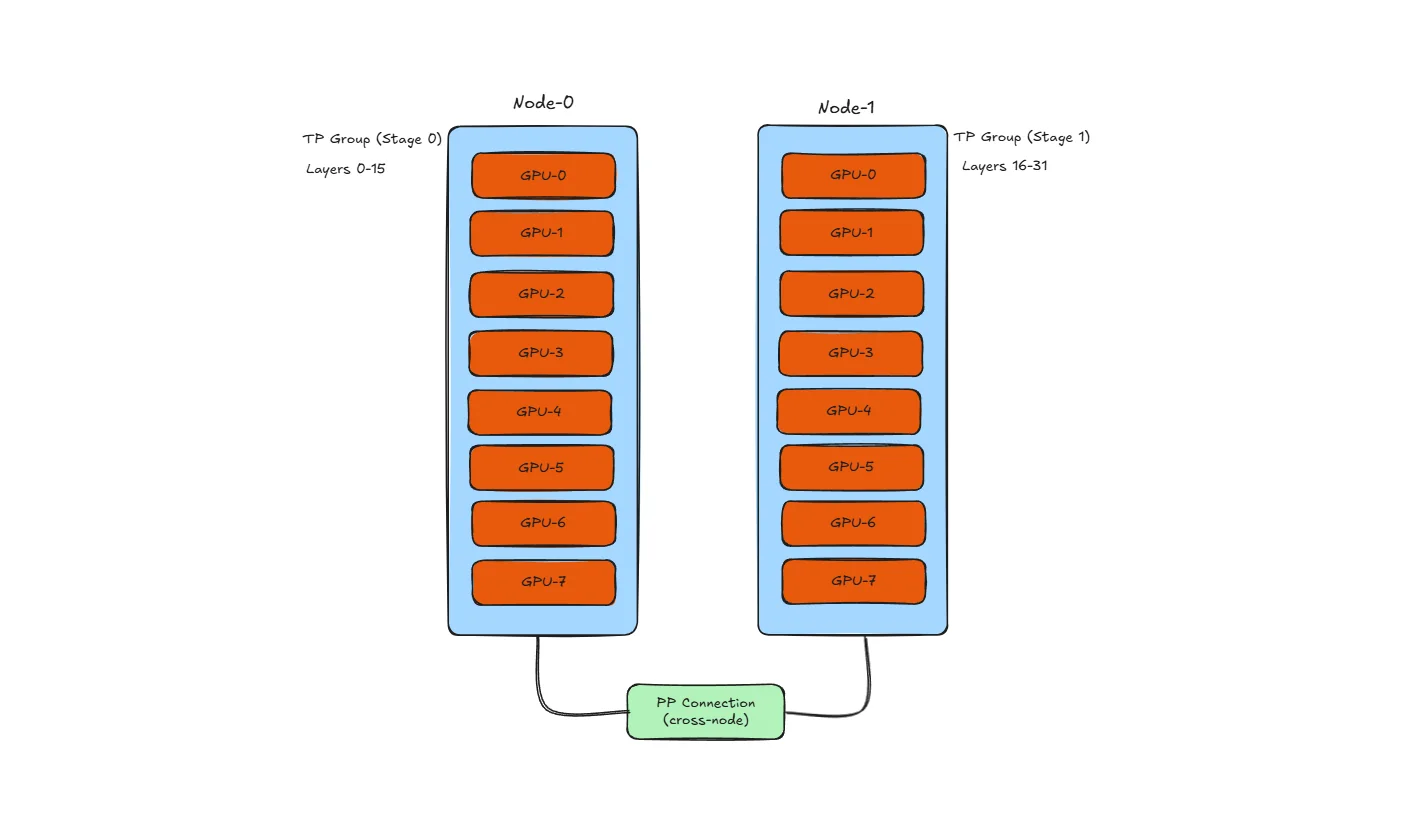
Parallelism Techniques for LLM Inference — AWS Neuron Documentation
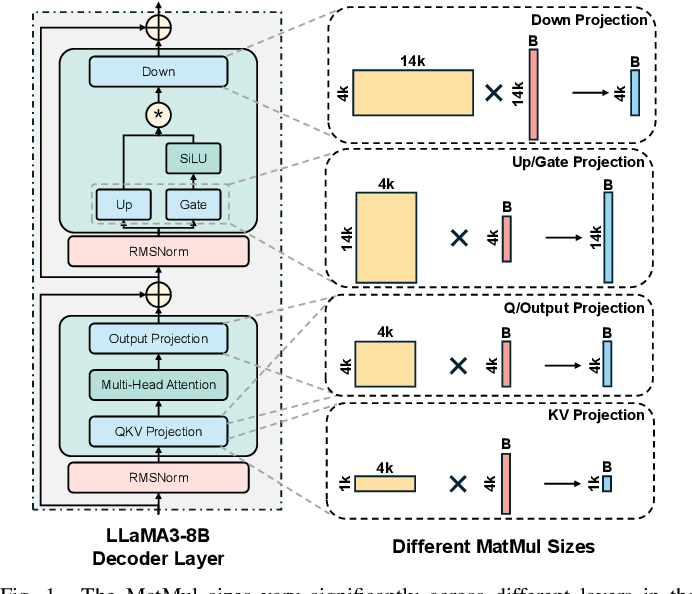
What do all these layers do in LLM? - Shchegrikovich LLM
Mastering LLM Techniques: Inference Optimization – GIXtools
Essential Practices for Building Robust LLM Pipelines
LLM 学习笔记-Deepspeed-MoE 论文 - marsggbo - 博客园
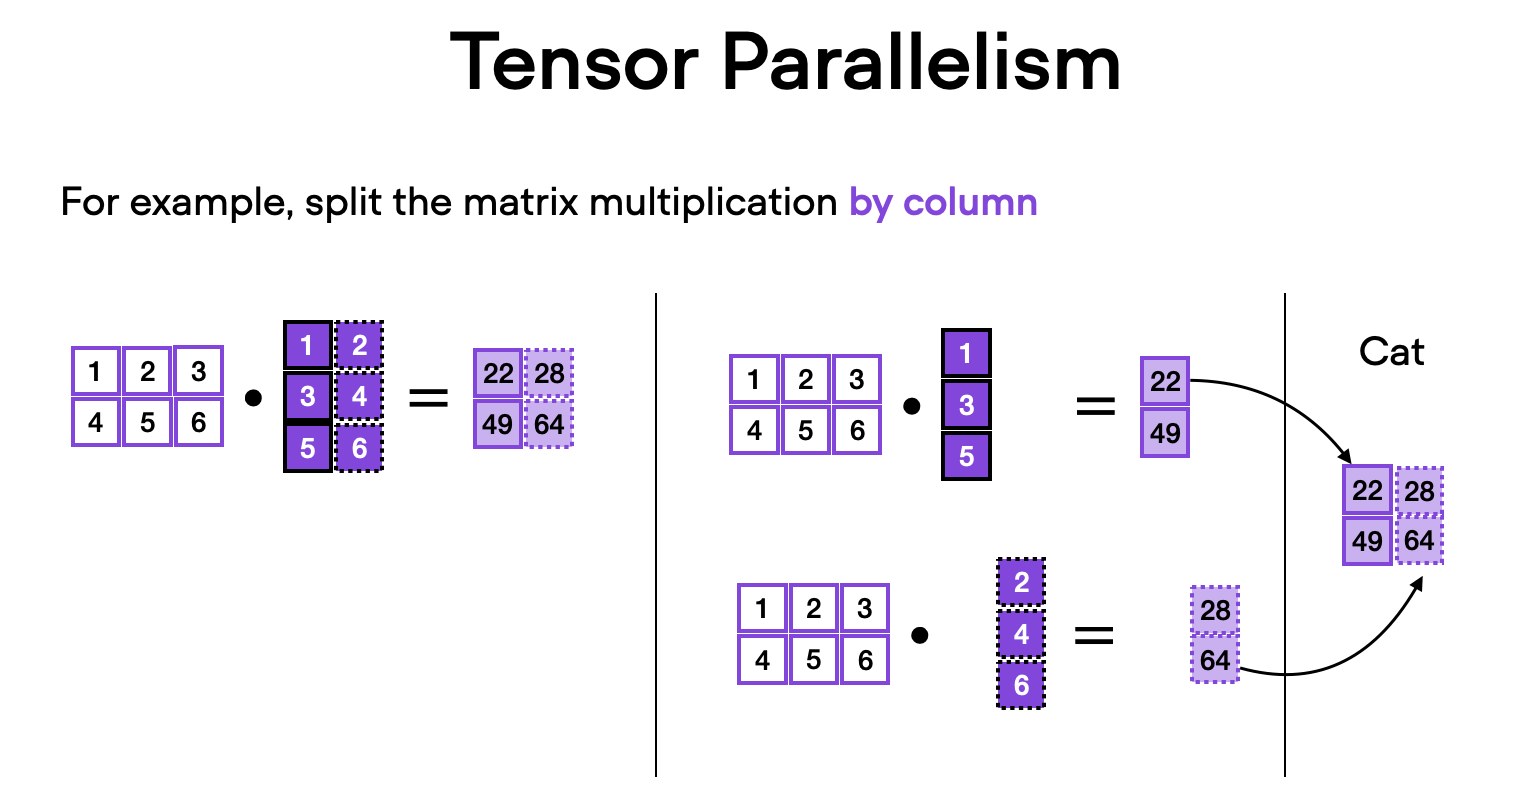
Demystifying Tensor Parallelism | Robot Chinwag
The 7 Layers of the LLM Stack | Gabriel Millien
Evolution Strategies at Scale: LLM Fine-Tuning Beyond Reinforcement ...
Rethinking LLM Reliability: Calibration, Compression, and the Hidden ...
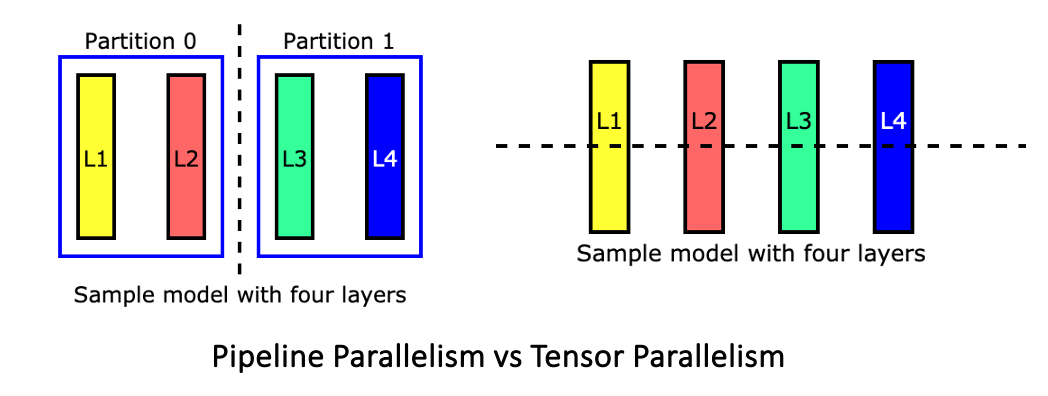
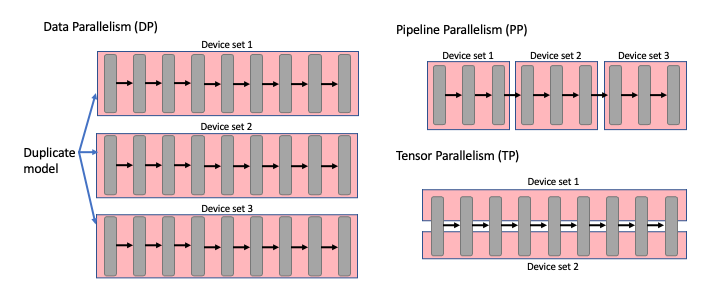
Model Parallelism vs Data Parallelism vs Tensor Parallelism | # ...
Scaling Expert Parallelism in TensorRT LLM (Part 3: Pushing the ...
Check out this 8-Layer Architecture for LLM Systems | Greg Coquillo
LLM并行策略(一)TP, Tensor Parallelism - 知乎
LLM Compressor: Optimize LLMs for low-latency deployments | Red Hat ...
[Literature Review] Scalable Synthesis of distributed LLM workloads ...
[实践] Tensor Parallel(精简版) - 知乎
Navigating LLM Deployment: Tips, Tricks, and Techniques - InfoQ
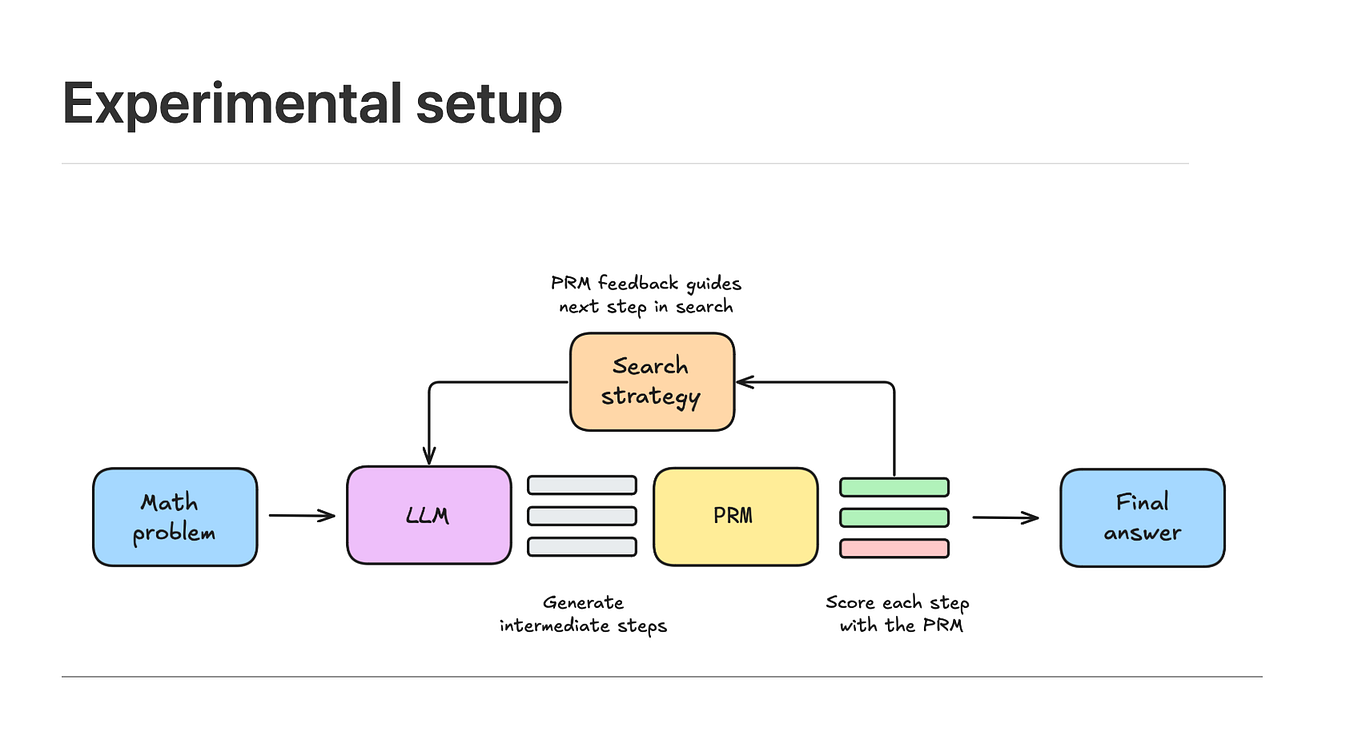
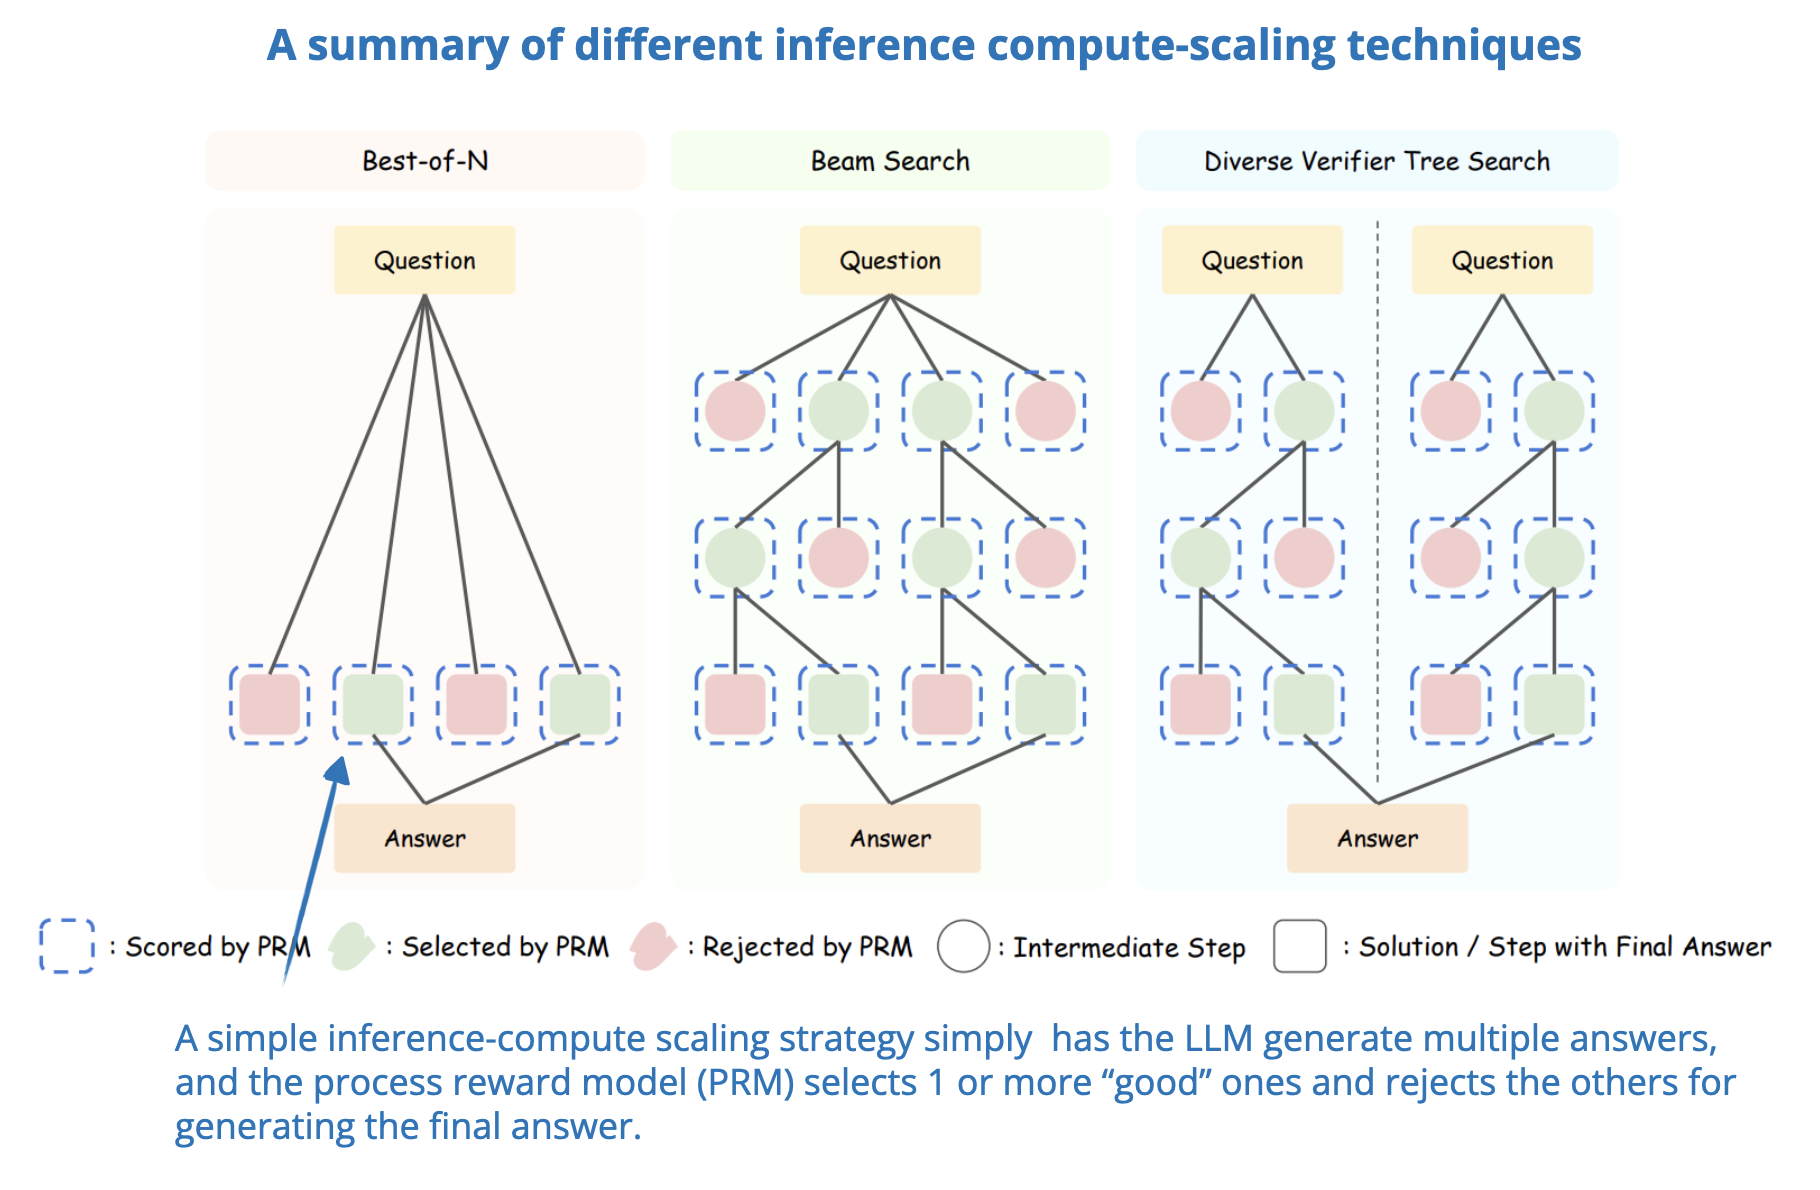
Scaling LLM Test Time Compute
Figure 1 from A Fast Optimization View: Reformulating Single Layer ...
LLM Architectures Explained: What Powers Today’s Top Models
[LLM] 张量并行Tensor Parallel - 知乎
Simplified representation of the most essential LLM components. (A ...
LLM Can Now Reason In Parallel: UC Berkeley And UCSF Researchers ...
Understanding Multimodal LLMs - by Sebastian Raschka, PhD
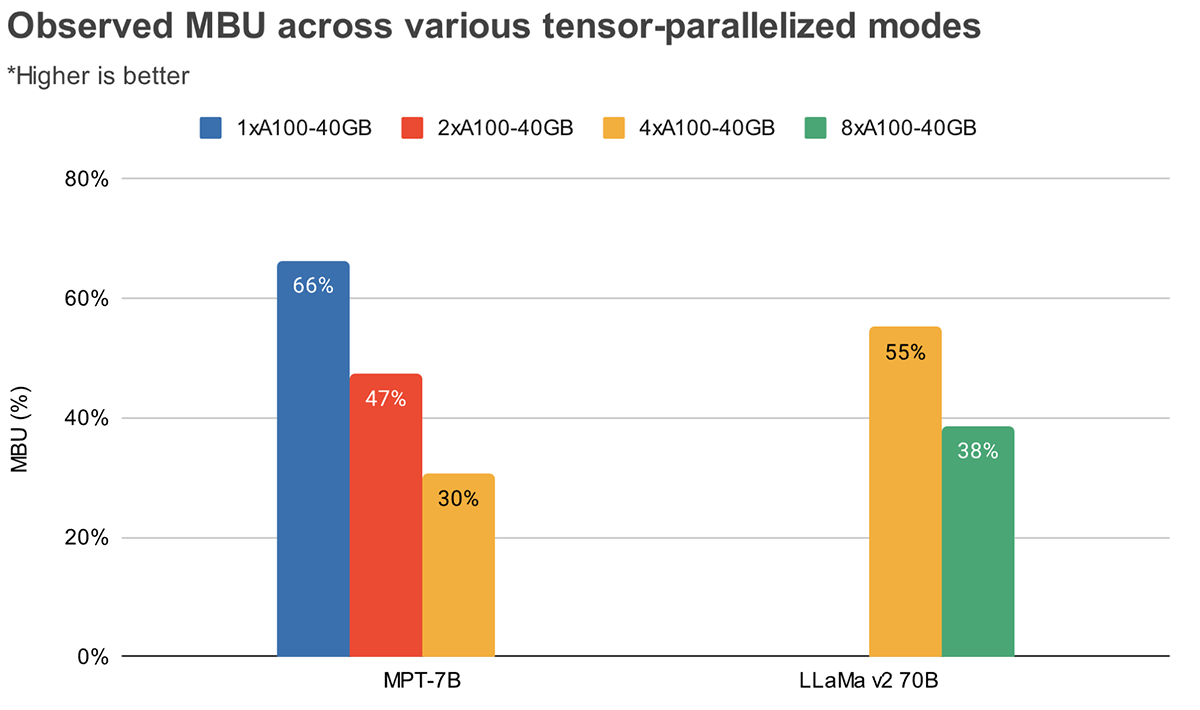
LLM Inference Performance Engineering: Best Practices | Databricks Blog
What Are Large Language Model Llm Agents And Autonomous Agents - Free ...
LLM Research Papers: The 2025 List (July to December)
Expert Parallelism and Mixed Parallelism Strategies in vLLM | Jarvis ...
Distributed vLLM Inference - Bristol Centre for Supercomputing ...
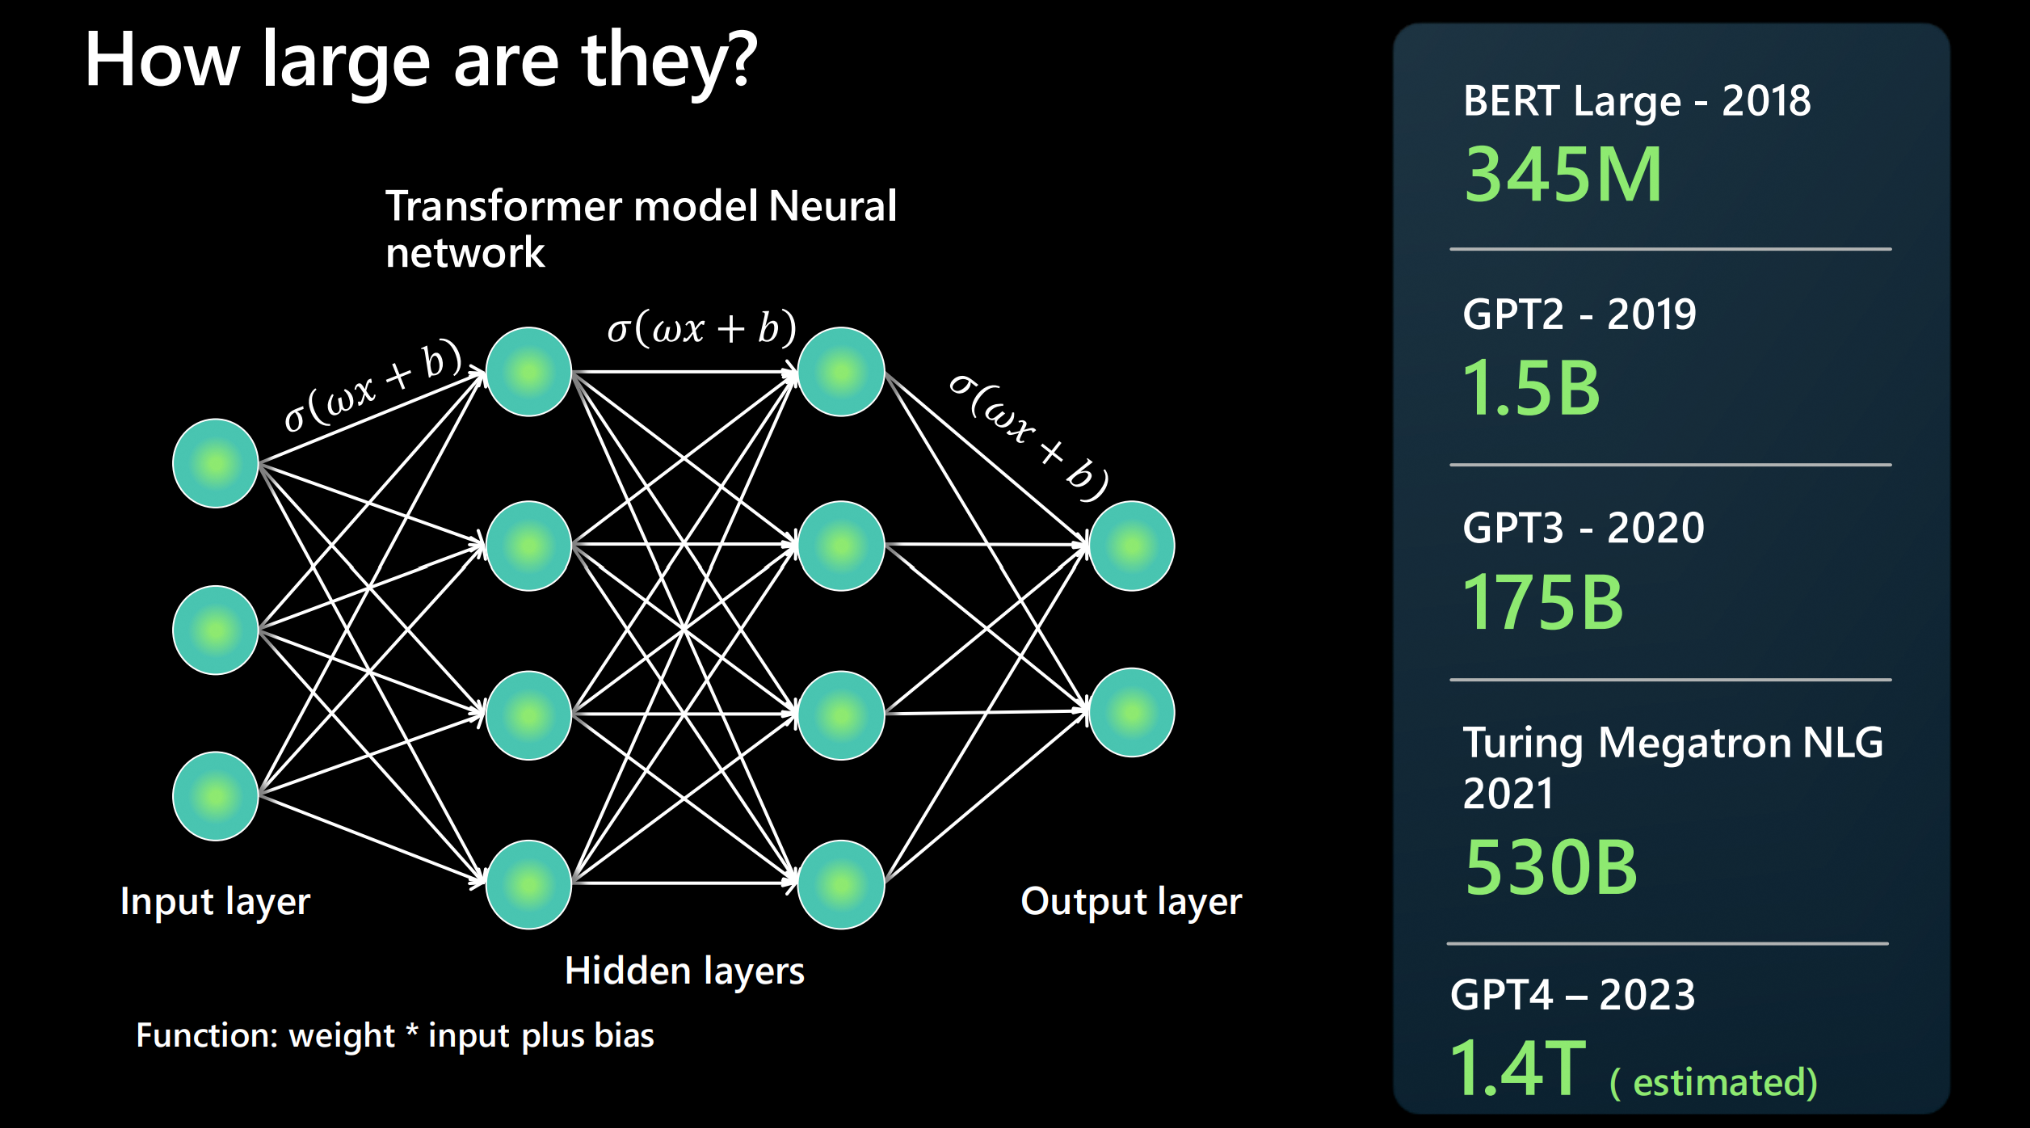
Scaling LLMs: GPT-3 and Beyond | AI Tutorial | Next Electronics
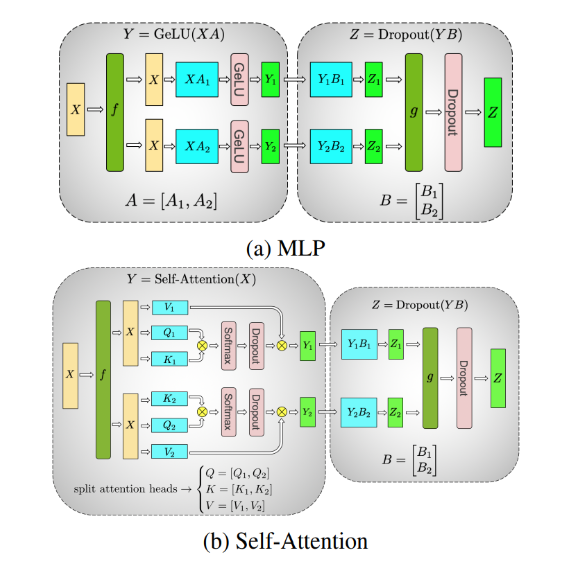
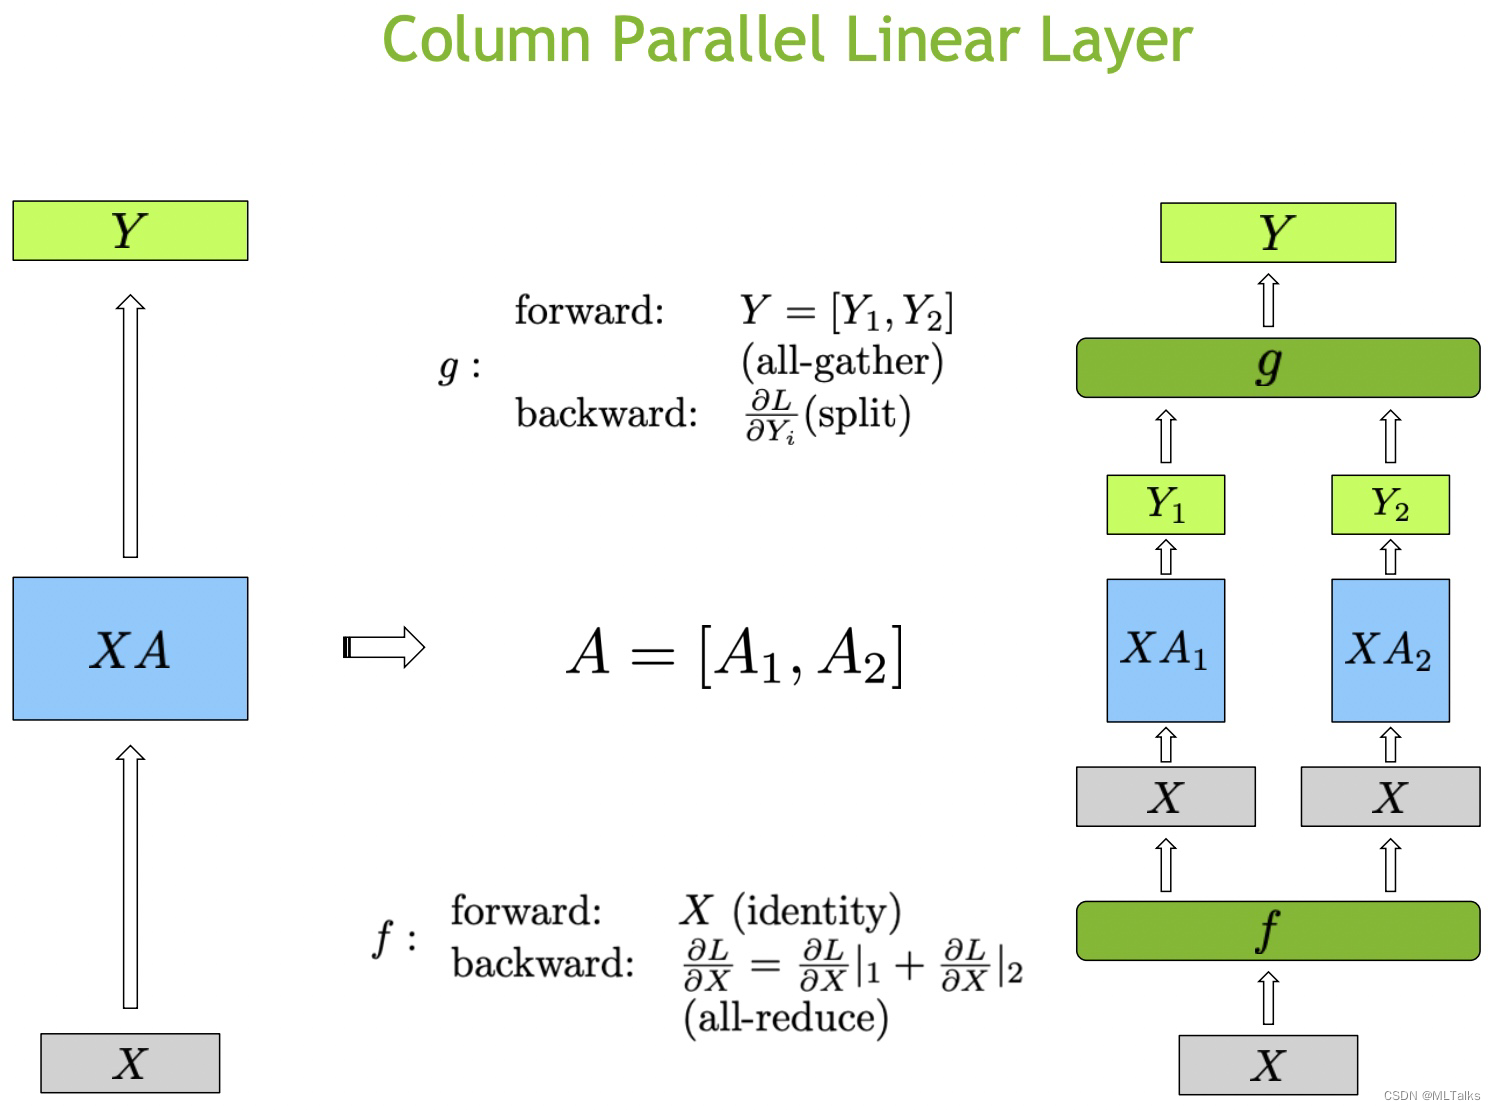
详解MegatronLM Tensor模型并行训练(Tensor Parallel)_megatron-lm-CSDN博客
LLM(六):GPT 的张量并行化(tensor parallelism)方案 - 知乎
MegaScale-Omni: A Hyper-Scale, Workload-Resilient System for MultiModal ...
[2410.02458] MedVisionLlama: Leveraging Pre-Trained Large Language ...
LLM(6):GPT 的张量并行化(tensor parallelism)方案 - 知乎
[论文评述] Nonuniform-Tensor-Parallelism: Mitigating GPU failure impact for ...
TACO: Efficient Communication Compression of Intermediate Tensors for ...
模型量化-llm量化 - 知乎
Comprehensive Guide to LLMs
Introduction to Model Parallelism - Amazon SageMaker AI
Medium
使用FasterTransformer实现LLM分布式推理 - 知乎
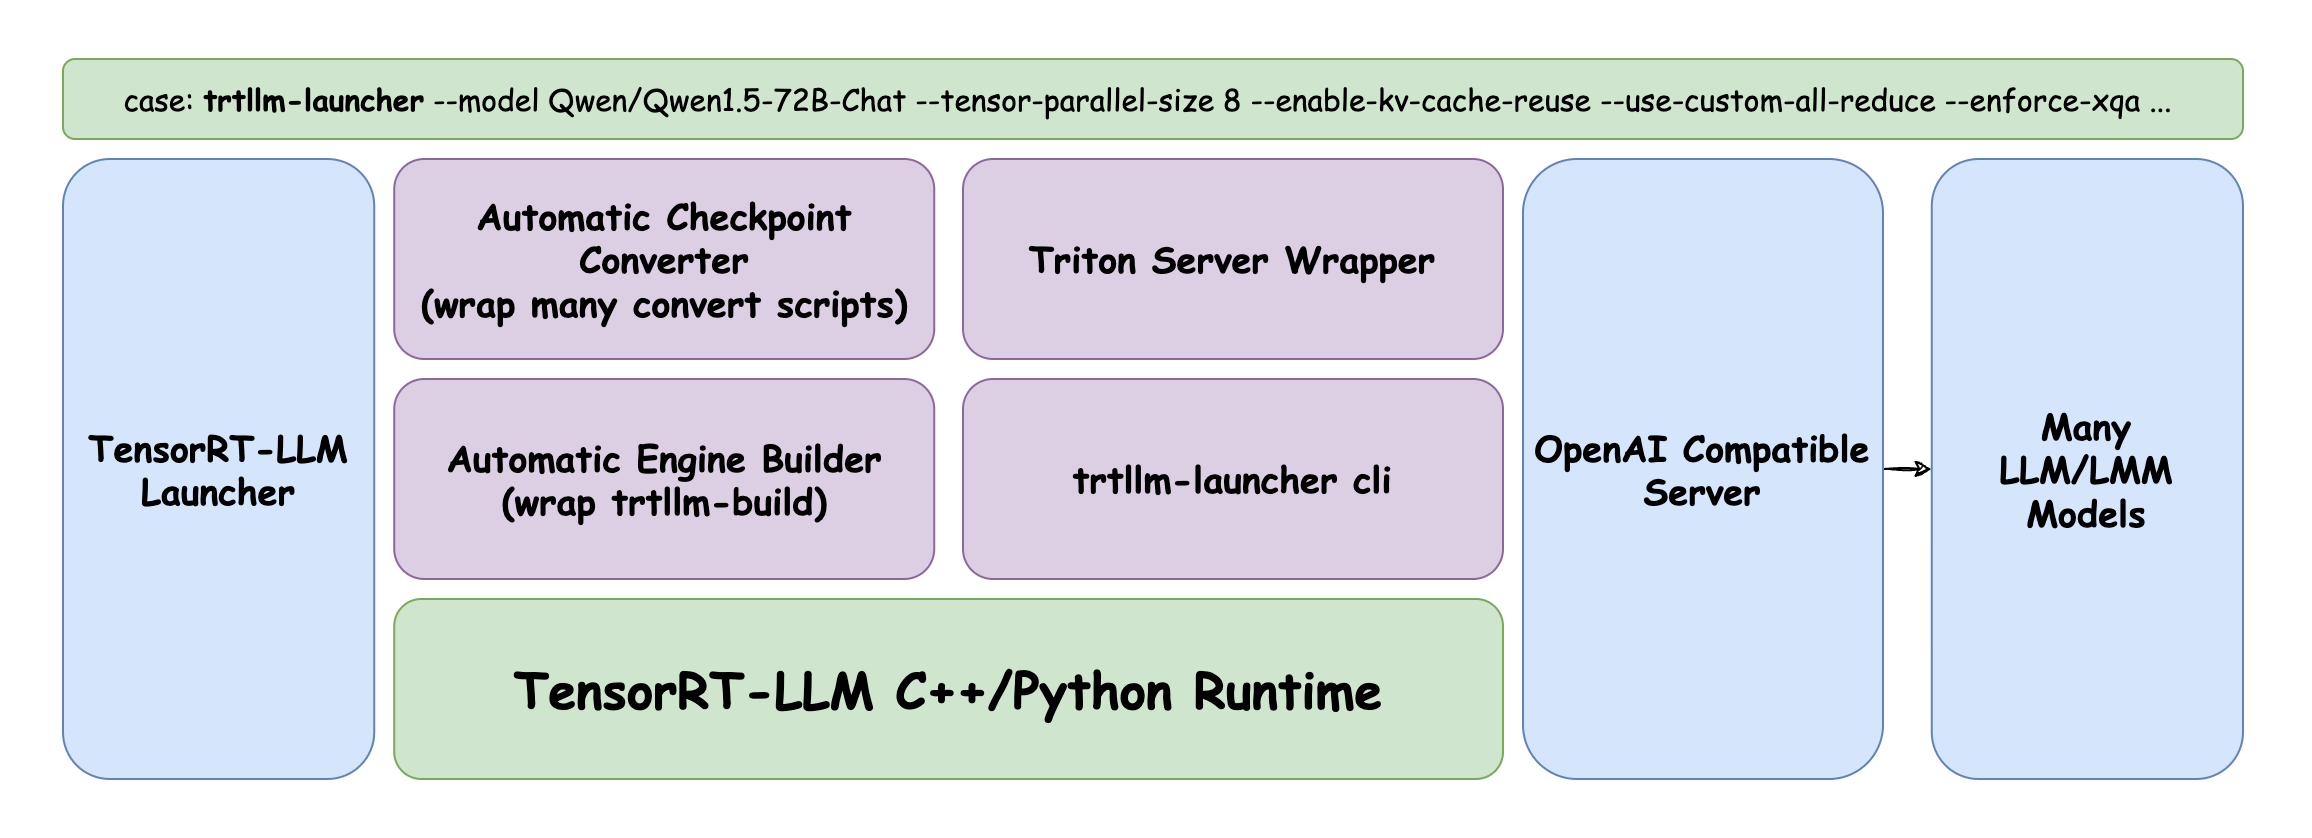
TensorRT-LLM 1.2最新特性:如何用1行代码实现10倍推理加速?_人工智能_我就是全世界-NVIDIA AI 技术专区
NLP(十八):LLM 的推理优化技术纵览_推理 pp并行-CSDN博客
[논문 리뷰] TACO: Efficient Communication Compression of Intermediate ...
[vLLM vs TensorRT-LLM] #9. Parallelism Strategies - The official ...
GitHub - FareedKhan-dev/llm-scale-deploy-guide: An end-to-end pipeline ...
大型语言模型(LLM)训练指南🚀 - 知乎
Inference-Time Compute Scaling Methods to Improve Reasoning Models ...
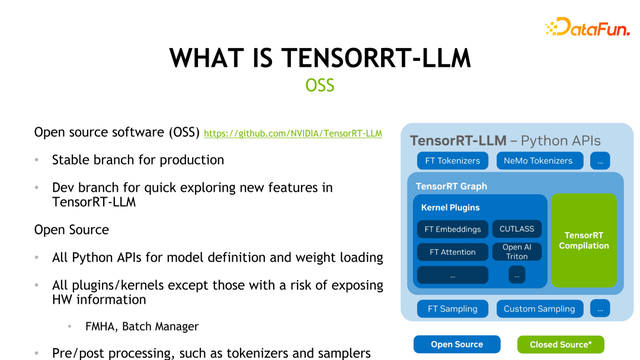
揭秘NVIDIA大模型推理框架:TensorRT-LLM - 知乎
TensorRT-LLM For All: A deep dive into getting started with NVidia’s ...
NVIDIA新推出的Tensor-LLM在优化大语言模型推理上有何突出之处?有大神可以分享一下吗? - 知乎
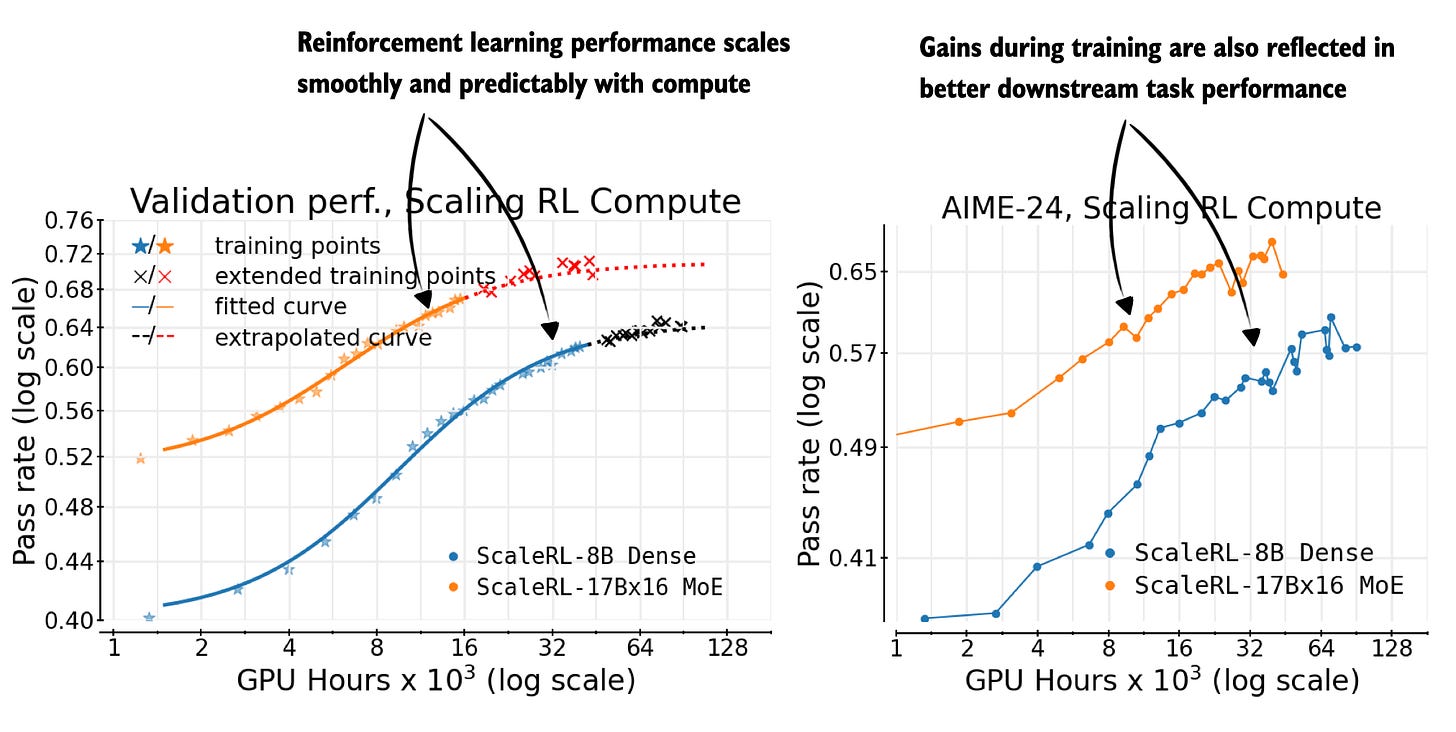
Scaling Laws for LLMs: From GPT-3 to o3
LLM:Scaling Laws for Neural Language Models (上)-CSDN博客
What do all these layers do in LLM?
Scaling Law Of Language Models | Towards Data Science